Run distributed experiments with Ray Tune#
Ray Tune is commonly used for large-scale distributed hyperparameter optimization. This page describes how to set up and launch a distributed experiment, and lists commonly used commands for running distributed experiments with Tune.
Summary#
To run a distributed experiment with Tune, do the following:
Start a Ray cluster if you haven’t already.
Run the script on the head node, or use ray submit or Ray Job Submission.
Example: Distributed Tune on AWS VMs#
The following example launches nodes on AWS with the Deep Learning AMI. For more information, see the cluster setup documentation. Save the following cluster configuration as tune-default.yaml:
cluster_name: tune-default
provider: {type: aws, region: us-west-2}
auth: {ssh_user: ubuntu}
min_workers: 3
max_workers: 3
# Deep Learning AMI (Ubuntu) Version 21.0
available_node_types:
  head_node:
    node_config: {InstanceType: c5.xlarge, ImageId: ami-0b294f219d14e6a82}
  worker_nodes:
    node_config: {InstanceType: c5.xlarge, ImageId: ami-0b294f219d14e6a82}
head_node_type: head_node
setup_commands: # Set up each node.
    - pip install ray torch torchvision tensorboard
ray up starts Ray on the cluster of nodes.
ray up tune-default.yaml
ray submit --start starts a cluster as specified by the given cluster configuration YAML file, uploads tune_script.py to the cluster, and runs python tune_script.py [args].
ray submit tune-default.yaml tune_script.py --start -- --ray-address=localhost:6379
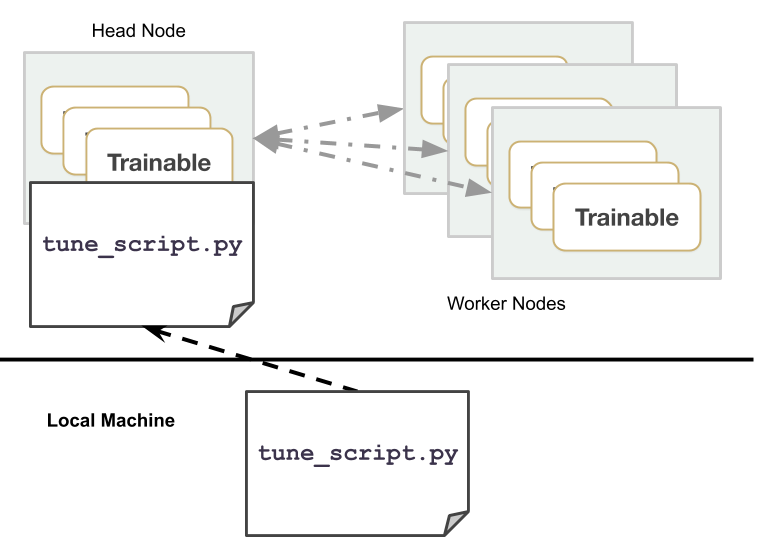
To analyze your results, start TensorBoard on the remote head node:
# Go to http://localhost:6006 to access TensorBoard.
ray exec tune-default.yaml 'tensorboard --logdir=~/ray_results/ --port 6006' --port-forward 6006
To customize the results directory, set storage_path in the RunConfig that you pass to Tuner, as in RunConfig(storage_path=...). Then point TensorBoard to that directory to visualize the results. You can also use awless to manage clusters on AWS.
Run a distributed Tune experiment#
A distributed, multi-node experiment requires Ray to be running already. You can start Ray on local machines or in the cloud.
Tune automatically detects the number of GPUs and CPUs across your machines, so you don’t need to manage CUDA_VISIBLE_DEVICES.
To run a distributed experiment, call ray.init(address=<address>) before Tuner.fit(), where <address> is the Ray address, which defaults to localhost:6379. Run the Tune Python script only on the head node of the Ray cluster.
One common way to make an existing Tune experiment distributed is to add an argparse argument, so you can toggle between distributed and single-node runs.
import ray
import argparse

parser = argparse.ArgumentParser()
parser.add_argument("--ray-address")
args = parser.parse_args()
ray.init(address=args.ray_address)

tuner = tune.Tuner(...)
tuner.fit()
# On the head node, connect to an existing ray cluster
python tune_script.py --ray-address=localhost:XXXX
If you started the cluster from a cluster configuration with ray up or ray submit --start, run the following command:
ray submit tune-default.yaml tune_script.py -- --ray-address=localhost:6379
Tip
The examples commonly use the Ray address
localhost:6379.If the Ray cluster is already running, you shouldn’t need to run anything on the worker nodes.
Configure storage for a distributed Tune run#
In a distributed experiment, try to use cloud checkpointing to reduce synchronization overhead. To do so, specify a remote storage_path in the RunConfig.
In the following example, my_trainable is a user-defined Ray Tune trainable:
from ray import tune
from my_module import my_trainable

tuner = tune.Tuner(
    my_trainable,
    run_config=tune.RunConfig(
        name="experiment_name",
        storage_path="s3://bucket-name/sub-path/",
    )
)
tuner.fit()
For more details or customization, see the guide on configuring storage in a distributed Tune experiment.
Run Tune on preemptible instances#
Running on spot instances, also called preemptible instances, can reduce the cost of your experiment. To enable spot instances on AWS, modify the cluster configuration as follows:
# Provider-specific config for worker nodes, e.g. instance type.
worker_nodes:
    InstanceType: m5.large
    ImageId: ami-0b294f219d14e6a82 # Deep Learning AMI (Ubuntu) Version 21.0

    # Run workers on spot by default. Comment this out to use on-demand.
    InstanceMarketOptions:
        MarketType: spot
        SpotOptions:
            MaxPrice: 1.0  # Max Hourly Price
On GCP, modify the cluster configuration as follows:
worker_nodes:
    machineType: n1-standard-2
    disks:
      - boot: true
        autoDelete: true
        type: PERSISTENT
        initializeParams:
          diskSizeGb: 50
          # See https://cloud.google.com/compute/docs/images for more images
          sourceImage: projects/deeplearning-platform-release/global/images/family/tf-1-13-cpu

    # Run workers on preemtible instances.
    scheduling:
      - preemptible: true
Spot instances might be preempted suddenly while trials are still running. To mitigate the effects, preserve the progress of your model training with Tune checkpointing.
search_space = {
    "lr": tune.sample_from(lambda spec: 10 ** (-10 * np.random.rand())),
    "momentum": tune.uniform(0.1, 0.9),
}

tuner = tune.Tuner(
    TrainMNIST,
    run_config=tune.RunConfig(stop={"training_iteration": 10}),
    param_space=search_space,
)
results = tuner.fit()
Example: Run Tune on AWS spot instances#
The following steps run Tune on spot instances. They assume you’ve already set up your AWS credentials with aws configure:
Download
mnist_pytorch_trainable.py, a full example Tune experiment script that includes a trainable with checkpointing. To run this example, install the following packages:pip install ray torch torchvision filelock
Download the example cluster configuration file,
tune-default.yaml.Run
ray submitas follows to run Tune across the nodes. Append--startif the cluster isn’t up yet. Append--stopto shut down your nodes automatically after the run.ray submit tune-default.yaml mnist_pytorch_trainable.py --start -- --ray-address=localhost:6379
Optionally, to test on AWS or GCP, run the following command to kill a random worker node after all the worker nodes are up:
ray kill-random-node tune-default.yaml --hard
To summarize, run the following commands:
wget https://raw.githubusercontent.com/ray-project/ray/master/python/ray/tune/examples/mnist_pytorch_trainable.py
wget https://raw.githubusercontent.com/ray-project/ray/master/python/ray/tune/examples/tune-default.yaml
ray submit tune-default.yaml mnist_pytorch_trainable.py --start -- --ray-address=localhost:6379

# wait a while until after all nodes have started
ray kill-random-node tune-default.yaml --hard
You should see Tune eventually continue the trials on a different worker node. For more details, see How does Tune handle failures?.
To upload results to cloud storage such as S3, set storage_path=... in the RunConfig that you pass to Tuner. This persists your results in case you want to start and stop your cluster automatically.
How does Tune handle failures?#
When max_failures isn’t 0, Tune automatically restarts failed trials, in both single-node and distributed settings.
For example, suppose a node is preempted or crashes while a trial is still running on that node. If a checkpoint for the trial exists, Tune waits until resources are available and then resumes the trial from where it left off. In the distributed setting, this also requires some form of persistent storage configured to access the trial’s checkpoint. If Tune finds no checkpoint, the trial restarts from scratch. For more information, see How to save and load trial checkpoints.
If the trial or actor is then placed on a different node, Tune automatically pushes the previous checkpoint file to that node and restores the remote trial actor state, so the trial resumes from the latest checkpoint even after a failure.
Recover from failures#
Tune automatically persists the progress of your entire experiment, which is one Tuner.fit() session. If an experiment crashes or is otherwise canceled, resume it with restore().
Common Tune commands#
For more comprehensive documentation of commands, see the Clusters page. The following commands are commonly used for submitting experiments:
# Upload `tune_experiment.py` from your local machine onto the cluster. Then,
# run `python tune_experiment.py --address=localhost:6379` on the remote machine.
ray submit CLUSTER.YAML tune_experiment.py -- --address=localhost:6379

# Start a cluster and run an experiment in a detached tmux session,
# and shut down the cluster as soon as the experiment completes.
# In `tune_experiment.py`, set `RunConfig(storage_path="s3://...")`
# to persist results
ray submit CLUSTER.YAML --tmux --start --stop tune_experiment.py -- --address=localhost:6379

# To start or update your cluster:
ray up CLUSTER.YAML [-y]

# Shut-down all instances of your cluster:
ray down CLUSTER.YAML [-y]

# Run TensorBoard and forward the port to your own machine.
ray exec CLUSTER.YAML 'tensorboard --logdir ~/ray_results/ --port 6006' --port-forward 6006

# Run Jupyter Lab and forward the port to your own machine.
ray exec CLUSTER.YAML 'jupyter lab --port 6006' --port-forward 6006

# Get a summary of all the experiments and trials that have executed so far.
ray exec CLUSTER.YAML 'tune ls ~/ray_results'

# Upload and sync file_mounts up to the cluster with this command.
ray rsync-up CLUSTER.YAML

# Download the results directory from your cluster head node to your local machine on ``~/cluster_results``.
ray rsync-down CLUSTER.YAML '~/ray_results' ~/cluster_results

# Launching multiple clusters using the same configuration.
ray up CLUSTER.YAML -n="cluster1"
ray up CLUSTER.YAML -n="cluster2"
ray up CLUSTER.YAML -n="cluster3"
Troubleshooting#
If your program freezes, run the following command to restart the Ray cluster without running any of the installation commands:
ray up CLUSTER.YAML --restart-only