Configure persistent storage#
A Ray Train run produces checkpoints that you can save to a persistent storage location.
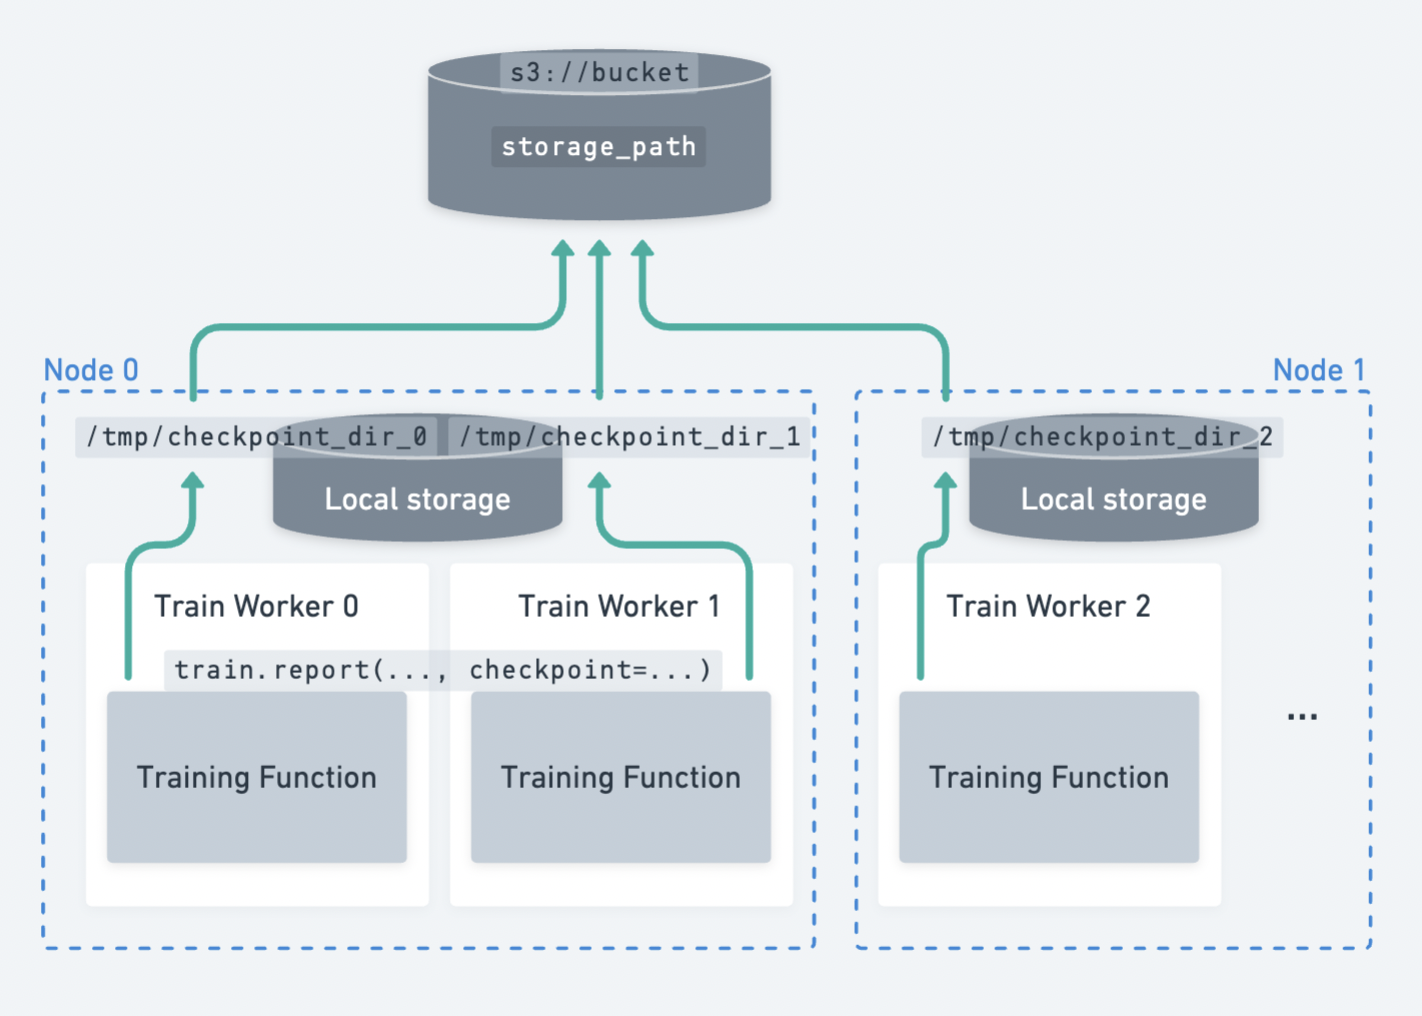
Multiple workers spread across multiple nodes upload checkpoints to persistent storage.#
Ray Train expects all workers to be able to write files to the same persistent storage location. For multi-node training, Ray Train therefore requires external persistent storage, such as cloud object storage or a shared filesystem. Cloud object storage options include Amazon S3, Google Cloud Storage, and Azure Blob Storage. Shared filesystem options include Amazon Elastic File System (EFS), Google Cloud Filestore, Azure Files, and Hadoop Distributed File System (HDFS).
Persistent storage supports checkpointing and fault tolerance. With checkpoints in persistent storage, you can resume training from the last checkpoint after a node failure. For details on setting up checkpointing, see Save and load checkpoints.
Persistent storage also supports post-experiment analysis, because it keeps data such as the best checkpoints and hyperparameter configurations in one location after the Ray cluster terminates. It also connects training and fine-tuning to downstream serving and batch inference. You can access the models and artifacts to share them with others or use them in downstream tasks.
Cloud object storage#
The Ray team recommends cloud object storage, such as Amazon S3, Google Cloud Storage, or Azure Blob Storage, for persisting Ray Train checkpoint files.
To use cloud object storage, set RunConfig(storage_path) to a storage container URI:
Specify a URI with the s3:// scheme. Ray Train uses PyArrow’s default S3FileSystem for upload and download.
from ray import train
from ray.train.torch import TorchTrainer

trainer = TorchTrainer(
    ...,
    run_config=train.RunConfig(
        storage_path="s3://bucket-name/sub-path/",
        name="experiment_name",
    )
)
Specify a URI with the gs:// scheme. Ray Train uses PyArrow’s default GcsFileSystem for upload and download.
from ray import train
from ray.train.torch import TorchTrainer

trainer = TorchTrainer(
    ...,
    run_config=train.RunConfig(
        storage_path="gs://bucket-name/sub-path/",
        name="experiment_name",
    )
)
Ray Train uses pyarrow.fs for storage I/O, so wrap adlfs.AzureBlobFileSystem in a pyarrow.fs.PyFileSystem and pass it as RunConfig(storage_filesystem). Use the abfss:// scheme, which enforces TLS, for the URI:
import adlfs
from pyarrow.fs import FSSpecHandler, PyFileSystem
from ray import train
from ray.train.torch import TorchTrainer

azure_fs = PyFileSystem(
    FSSpecHandler(adlfs.AzureBlobFileSystem(account_name="account-name"))
)

trainer = TorchTrainer(
    ...,
    run_config=train.RunConfig(
        storage_filesystem=azure_fs,
        storage_path="abfss://container@account.dfs.core.windows.net/sub-path/",
        name="experiment_name",
    )
)
For details on storage_filesystem, see Custom storage.
Make sure that all nodes in the Ray cluster can access the storage container, so workers can upload their outputs to a shared location. In the preceding AWS S3 example, all files go to shared storage at s3://bucket-name/sub-path/experiment_name for further processing.
Local storage#
How Ray Train uses local storage depends on whether your cluster has one node or several.
Single-node clusters#
If you run an experiment on a single node, such as a laptop, Ray Train uses the local filesystem as the storage location for checkpoints and other artifacts. By default, Ray Train saves results to ~/ray_results in a subdirectory with a unique, auto-generated name. To customize this location, set storage_path and name in RunConfig.
from ray import train
from ray.train.torch import TorchTrainer

trainer = TorchTrainer(
    ...,
    run_config=train.RunConfig(
        storage_path="/tmp/custom/storage/path",
        name="experiment_name",
    )
)
In this example, you can find all experiment results locally at /tmp/custom/storage/path/experiment_name for further processing.
Multi-node clusters#
Warning
When you run on multiple nodes, Ray Train no longer supports using the local filesystem of the head node as the persistent storage location.
If you save checkpoints with ray.train.report(..., checkpoint=...) and run on a multi-node cluster, Ray Train raises an error if NFS or cloud storage isn’t set up, because Ray Train expects all workers to be able to write the checkpoint to the same persistent storage location.
If your training loop doesn’t save checkpoints, Ray Train still aggregates the reported metrics to the local storage path on the head node.
For details, see GitHub issue #37177.
Custom storage#
If the preceding options don’t suit your needs, Ray Train supports custom filesystems and custom logic. Ray Train standardizes on the pyarrow.fs.FileSystem interface to interact with storage. See the pyarrow.fs.FileSystem API reference.
By default, passing storage_path=s3://bucket-name/sub-path/ uses PyArrow’s default S3 filesystem implementation to upload files. See also PyArrow’s other default filesystem implementations.
Implement custom storage upload and download logic by providing an implementation of pyarrow.fs.FileSystem to RunConfig(storage_filesystem).
Warning
When you provide a custom filesystem, set the associated storage_path to a qualified filesystem path without the protocol prefix.
For example, if you provide a custom S3 filesystem for s3://bucket-name/sub-path/, set storage_path to bucket-name/sub-path/, with the s3:// stripped. The following example shows this usage.
import pyarrow.fs

from ray import train
from ray.train.torch import TorchTrainer

fs = pyarrow.fs.S3FileSystem(
    endpoint_override="http://localhost:9000",
    access_key=...,
    secret_key=...
)

trainer = TorchTrainer(
    ...,
    run_config=train.RunConfig(
        storage_filesystem=fs,
        storage_path="bucket-name/sub-path",
        name="unique-run-id",
    )
)
fsspec filesystems#
fsspec offers many filesystem implementations, such as s3fs and gcsfs.
To use any of these implementations, wrap the fsspec filesystem with a pyarrow.fs utility:
# Make sure to install: `pip install -U s3fs`
import s3fs
import pyarrow.fs

s3_fs = s3fs.S3FileSystem(
    key='miniokey...',
    secret='asecretkey...',
    endpoint_url='https://...'
)
custom_fs = pyarrow.fs.PyFileSystem(pyarrow.fs.FSSpecHandler(s3_fs))

run_config = RunConfig(storage_path="minio_bucket", storage_filesystem=custom_fs)
See also
See the API references for the pyarrow.fs wrapper utilities:
S3-compatible storage#
For S3-compatible stores such as Backblaze B2 or MinIO, follow the preceding custom filesystem examples, or pass the endpoint as a query parameter in the storage_path URI:
from ray import train
from ray.train.torch import TorchTrainer

trainer = TorchTrainer(
    ...,
    run_config=train.RunConfig(
        # Backblaze B2 (substitute your bucket's region):
        storage_path="s3://bucket-name/sub-path?endpoint_override=https://s3.us-west-001.backblazeb2.com",
        # MinIO running locally:
        # storage_path="s3://bucket-name/sub-path?endpoint_override=http://localhost:9000",
        name="unique-run-id",
    )
)
Alternatively, configure the endpoint and credentials through the environment variables that Arrow reads, and use a plain storage_path="s3://bucket/path". See Arrow’s S3 environment variables. For Backblaze B2, set AWS_ENDPOINT_URL_S3 to your bucket’s endpoint, and set AWS_ACCESS_KEY_ID and AWS_SECRET_ACCESS_KEY to your B2 application key ID and key.
For a worked Backblaze B2 example, see the Backblaze B2 end-to-end notebook.
Overview of Ray Train outputs#
The preceding sections cover how to configure the storage location for Ray Train outputs. The following example shows what these outputs are and how Ray Train structures them in storage.
See also
This example includes checkpointing, which Save and load checkpoints covers in detail.
import os
import tempfile

import ray.train
from ray.train import Checkpoint
from ray.train.torch import TorchTrainer

def train_fn(config):
    for i in range(10):
        # Training logic here
        metrics = {"loss": ...}

        with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
            torch.save(..., os.path.join(temp_checkpoint_dir, "checkpoint.pt"))
            train.report(
                metrics,
                checkpoint=Checkpoint.from_directory(temp_checkpoint_dir)
            )

trainer = TorchTrainer(
    train_fn,
    scaling_config=ray.train.ScalingConfig(num_workers=2),
    run_config=ray.train.RunConfig(
        storage_path="s3://bucket-name/sub-path/",
        name="unique-run-id",
    )
)
result: train.Result = trainer.fit()
last_checkpoint: Checkpoint = result.checkpoint
Ray Train persists the following files to storage:
{RunConfig.storage_path}  (ex: "s3://bucket-name/sub-path/")
└── {RunConfig.name}      (ex: "unique-run-id")               <- Train run output directory
    ├── *_snapshot.json                                       <- Train run metadata files (DeveloperAPI)
    ├── checkpoint_epoch=0/                                   <- Checkpoints
    ├── checkpoint_epoch=1/
    └── ...
The Result and Checkpoint objects that trainer.fit returns are the easiest way to access the data in these files:
result.filesystem, result.path
# S3FileSystem, "bucket-name/sub-path/unique-run-id"

result.checkpoint.filesystem, result.checkpoint.path
# S3FileSystem, "bucket-name/sub-path/unique-run-id/checkpoint_epoch=0"
For a full guide to working with training Results, see Inspect training results.
Advanced configuration#
Keep the original current working directory#
Ray Train changes the current working directory of each worker to the same path.
By default, this path is a subdirectory of the Ray session directory, for example /tmp/ray/session_latest. Ray also writes its other logs and temporary files to the session directory. You can customize the location of the Ray session directory.
To stop Ray Train from changing the current working directory, set the RAY_CHDIR_TO_TRIAL_DIR=0 environment variable.
Disable this behavior when you want your training workers to access relative paths from the directory you launched the training script from.
Tip
When you run on a distributed cluster, make sure that all workers have a mirrored working directory so they can access the same relative paths.
One way to do this is to set the working directory in the Ray runtime environment.
import os

import ray
import ray.train
from ray.train.torch import TorchTrainer

os.environ["RAY_CHDIR_TO_TRIAL_DIR"] = "0"

# Write some file in the current working directory
with open("./data.txt", "w") as f:
    f.write("some data")

# Set the working directory in the Ray runtime environment
ray.init(runtime_env={"working_dir": "."})

def train_fn_per_worker(config):
    # Check that each worker can access the working directory
    # NOTE: The working directory is copied to each worker and is read only.
    assert os.path.exists("./data.txt"), os.getcwd()

trainer = TorchTrainer(
    train_fn_per_worker,
    scaling_config=ray.train.ScalingConfig(num_workers=2),
    run_config=ray.train.RunConfig(
        # storage_path=...,
    ),
)
trainer.fit()
Deprecated#
The following sections describe behavior that’s deprecated as of Ray 2.43 and that Ray Train V2 doesn’t support. Ray Train V2 is an overhaul of Ray Train’s implementation and select APIs.
For details, see the following resources:
Ray Train V2 REP: The Ray Enhancement Proposal that describes the technical details of the API change.
Ray Train V2 migration guide: The full guide that explains how to migrate to Ray Train V2.
Deprecated: Persist training artifacts#
Note
Persisting training worker artifacts is deprecated as of Ray 2.43. The feature relied on Ray Tune’s local working directory abstraction, which copied the local files of each worker to storage. Ray Train V2 decouples the two libraries, so this API, which already provided limited value, is deprecated.
Your training loop can save artifacts to the worker’s current working directory. For example, when you train a Stable Diffusion model, you might periodically save sample generated images as training artifacts.
By default, Ray Train changes the current working directory of each worker to a directory inside the run’s local staging directory, so all distributed training workers share the same absolute path as the working directory. To disable this default behavior so your training workers keep their original working directories, see Keep the original current working directory.
If you set RunConfig(SyncConfig(sync_artifacts=True)), Ray Train persists all artifacts saved in this directory to storage.
Configure the frequency of artifact syncing through SyncConfig. This behavior is off by default.
The following example shows the Train run output directory with the worker artifacts:
s3://bucket-name/sub-path (RunConfig.storage_path)
└── experiment_name (RunConfig.name)          <- The "experiment directory"
    ├── experiment_state-*.json
    ├── basic-variant-state-*.json
    ├── trainer.pkl
    ├── tuner.pkl
    └── TorchTrainer_46367_00000_0_...        <- The "trial directory"
        ├── events.out.tfevents...            <- Tensorboard logs of reported metrics
        ├── result.json                       <- JSON log file of reported metrics
        ├── checkpoint_000000/                <- Checkpoints
        ├── checkpoint_000001/
        ├── ...
        ├── artifact-rank=0-iter=0.txt        <- Worker artifacts
        ├── artifact-rank=1-iter=0.txt
        └── ...
Warning
Ray Train syncs the artifacts that every worker saves to storage. If multiple workers share the same node, make sure that they don’t delete files within their shared working directory.
As a best practice, write artifacts from only a single worker unless you need artifacts from multiple workers.
from ray import train

if train.get_context().get_world_rank() == 0:
    # Only the global rank 0 worker saves artifacts.
    ...

if train.get_context().get_local_rank() == 0:
    # Every local rank 0 worker saves artifacts.
    ...
Deprecated: Set the local staging directory#
Note
This section describes behavior that depends on Ray Tune implementation details and no longer applies to Ray Train V2.
Warning
Before Ray 2.10, you could set the RAY_AIR_LOCAL_CACHE_DIR environment variable or RunConfig(local_dir) to move the local staging directory out of ~/ray_results in your home directory.
Ray Train no longer uses these settings to configure the local staging directory. Use RunConfig(storage_path) to configure where your run’s outputs go.
Apart from files such as checkpoints that it writes directly to the storage_path, Ray Train also writes some log files and metadata files to an intermediate local staging directory, then copies or uploads them to the storage_path. Ray Train sets the current working directory of each worker within this local staging directory.
By default, the local staging directory is a subdirectory of the Ray session directory, for example /tmp/ray/session_latest. Ray also writes other temporary files to the session directory.
Customize the location of the staging directory by setting the location of the temporary Ray session directory.
The following example shows the structure of the local staging directory:
/tmp/ray/session_latest/artifacts/<ray-train-job-timestamp>/
└── experiment_name
    ├── driver_artifacts    <- These are all uploaded to storage periodically
    │   ├── Experiment state snapshot files needed for resuming training
    │   └── Metrics logfiles
    └── working_dirs        <- These are uploaded to storage if `SyncConfig(sync_artifacts=True)`
        └── Current working directory of training workers, which contains worker artifacts
Warning
You shouldn’t need to look into the local staging directory. The storage_path should be the only path that you need to interact with.
The structure of the local staging directory is subject to change in future versions of Ray Train. Don’t rely on these local staging files in your application.