Data loading and preprocessing#
Ray Train integrates with Ray Data for scalable, streaming data loading and preprocessing of large datasets. Ray Data provides the following advantages:
Streaming data loading and preprocessing, scalable to petabyte-scale data.
Scaling out heavy data preprocessing to CPU nodes, to avoid bottlenecking GPU training.
Automatic and fast failure recovery.
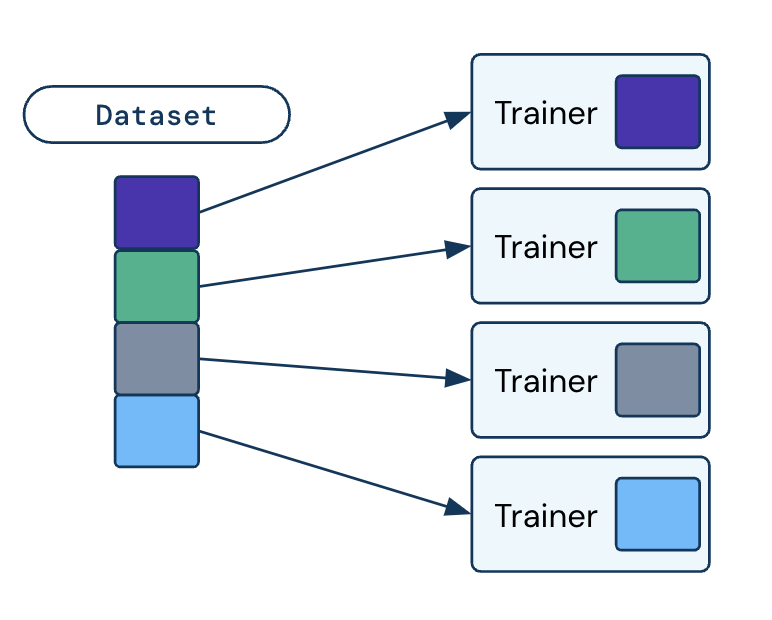
Automatic on-the-fly data splitting across distributed training workers.
For details, see the Ray Data documentation.
Note
Besides Ray Data, you can use framework-native data utilities with Ray Train, such as PyTorch Dataset, Hugging Face Dataset, and Lightning DataModule.
This guide covers how to add Ray Data to your Ray Train script and how to customize your data ingestion pipeline.
Quickstart#
Install Ray Data and Ray Train:
pip install -U "ray[data,train]"
Set up data ingestion in four steps:
Create a Ray Dataset from your input data.
Apply preprocessing operations to your Ray Dataset.
Pass the preprocessed dataset to the Ray Train trainer, which splits it equally across the distributed training workers in a streaming fashion.
Consume the Ray Dataset in your training function.
import torch
import ray
from ray import train
from ray.train import Checkpoint, ScalingConfig
from ray.train.torch import TorchTrainer

# Set this to True to use GPU.
# If False, do CPU training instead of GPU training.
use_gpu = False

# Step 1: Create a Ray Dataset from in-memory Python lists.
# You can also create a Ray Dataset from many other sources and file
# formats.
train_dataset = ray.data.from_items([{"x": [x], "y": [2 * x]} for x in range(200)])

# Step 2: Preprocess your Ray Dataset.
def increment(batch):
    batch["y"] = batch["y"] + 1
    return batch

train_dataset = train_dataset.map_batches(increment, batch_size="auto")


def train_func():
    batch_size = 16

    # Step 4: Access the dataset shard for the training worker via
    # ``get_dataset_shard``.
    train_data_shard = train.get_dataset_shard("train")
    # `iter_torch_batches` returns an iterable object that
    # yield tensor batches. Ray Data automatically moves the Tensor batches
    # to GPU if you enable GPU training.
    train_dataloader = train_data_shard.iter_torch_batches(
        batch_size=batch_size, dtypes=torch.float32
    )

    for epoch_idx in range(1):
        for batch in train_dataloader:
            inputs, labels = batch["x"], batch["y"]
            assert type(inputs) == torch.Tensor
            assert type(labels) == torch.Tensor
            assert inputs.shape[0] == batch_size
            assert labels.shape[0] == batch_size
            # Only check one batch for demo purposes.
            # Replace the above with your actual model training code.
            break

# Step 3: Create a TorchTrainer. Specify the number of training workers and
# pass in your Ray Dataset.
# The Ray Dataset is automatically split across all training workers.
trainer = TorchTrainer(
    train_func,
    datasets={"train": train_dataset},
    scaling_config=ScalingConfig(num_workers=2, use_gpu=use_gpu)
)
result = trainer.fit()
from ray import train

# Create the train and validation datasets.
train_data = ray.data.read_csv("./train.csv")
val_data = ray.data.read_csv("./validation.csv")

def train_func_per_worker():
    # Access Ray datasets in your train_func via ``get_dataset_shard``.
    # Ray Train shards all datasets across workers by default.
    train_ds = train.get_dataset_shard("train")
    val_ds = train.get_dataset_shard("validation")

    # Create Ray dataset iterables via ``iter_torch_batches``.
    train_dataloader = train_ds.iter_torch_batches(batch_size=16)
    val_dataloader = val_ds.iter_torch_batches(batch_size=16)

    ...

    trainer = pl.Trainer(
        # ...
    )

    # Feed the Ray dataset iterables to ``pl.Trainer.fit``.
    trainer.fit(
        model,
        train_dataloaders=train_dataloader,
        val_dataloaders=val_dataloader
    )

trainer = TorchTrainer(
    train_func,
    # You can pass in multiple datasets to the Trainer.
    datasets={"train": train_data, "validation": val_data},
    scaling_config=ScalingConfig(num_workers=4),
)
trainer.fit()
import ray
import ray.train
from huggingface_hub import HfFileSystem

...

# Create the train and evaluation datasets using HfFileSystem.
fs = HfFileSystem()
train_data = ray.data.read_parquet("hf://datasets/your-dataset/train/", filesystem=fs)
eval_data = ray.data.read_parquet("hf://datasets/your-dataset/validation/", filesystem=fs)

def train_func():
    # Access Ray datasets in your train_func via ``get_dataset_shard``.
    # Ray Train shards all datasets across workers by default.
    train_ds = ray.train.get_dataset_shard("train")
    eval_ds = ray.train.get_dataset_shard("evaluation")

    # Create Ray dataset iterables via ``iter_torch_batches``.
    train_iterable_ds = train_ds.iter_torch_batches(batch_size=16)
    eval_iterable_ds = eval_ds.iter_torch_batches(batch_size=16)

    ...

    args = transformers.TrainingArguments(
        ...,
        max_steps=max_steps # Required for iterable datasets
    )

    trainer = transformers.Trainer(
        ...,
        model=model,
        train_dataset=train_iterable_ds,
        eval_dataset=eval_iterable_ds,
    )

    # Prepare your Transformers Trainer
    trainer = ray.train.huggingface.transformers.prepare_trainer(trainer)
    trainer.train()

trainer = TorchTrainer(
    train_func,
    # You can pass in multiple datasets to the Trainer.
    datasets={"train": train_data, "evaluation": val_data},
    scaling_config=ScalingConfig(num_workers=4, use_gpu=True),
)
trainer.fit()
Load data#
You can create Ray Datasets from many data sources and formats. For details, see Loading data.
Preprocess data#
Ray Data supports a wide range of preprocessing operations that you can use to transform data before training.
For general preprocessing, see Transforming data.
For tabular data, see Preprocessing structured data.
For PyTorch tensors, see Return Torch tensors from transformations.
To optimize expensive preprocessing operations, see Cache the preprocessed dataset.
Input and split data#
Pass your preprocessed datasets to a Ray Train trainer, such as TorchTrainer, through the datasets argument.
To access the datasets you passed to the trainer’s datasets argument, call ray.train.get_dataset_shard() inside the train_loop_per_worker that runs on each distributed training worker.
Ray Train splits all datasets across the training workers by default. get_dataset_shard() returns 1/n of the dataset, where n is the number of training workers.
Ray Data splits the data on the fly in a streaming fashion.
Note
Because Ray Train splits the evaluation dataset, you have to aggregate the evaluation results across workers. You might use TorchMetrics or similar utilities in other frameworks. For an example, see Get started with DeepSpeed.
To override this behavior, pass the dataset_config argument. For details on configuring splitting logic, see Split datasets.
Consume data#
Inside train_loop_per_worker, each worker accesses its shard of the dataset through ray.train.get_dataset_shard().
You can consume this data in several ways, including the following:
To create a generic iterable of batches, call
iter_batches().To create a replacement for a PyTorch DataLoader, call
iter_torch_batches().
For details on iterating over your data, see Iterating over data.
Start with PyTorch data#
Some frameworks provide their own dataset and data loading utilities, such as the following:
PyTorch: Dataset and DataLoader
Hugging Face: Dataset
PyTorch Lightning: LightningDataModule
You can use these framework data utilities directly with Ray Train.
The following table compares these concepts at a high level.
PyTorch API |
Hugging Face API |
Ray Data API |
|---|---|---|
n/a |
For details, see the tab for your framework.
To use your PyTorch Dataset with Ray Data, do the following:
Convert your PyTorch Dataset to a Ray Dataset.
Pass the Ray Dataset to
TorchTrainerthrough thedatasetsargument.Inside your
train_loop_per_worker, access the dataset throughray.train.get_dataset_shard().Create a dataset iterable through
ray.data.DataIterator.iter_torch_batches().
For details, see Migrate from PyTorch Datasets and DataLoaders.
To use the PyTorch Dataset and DataLoader without Ray Data, do the following:
Instantiate the PyTorch Dataset and DataLoader directly in the
train_loop_per_worker.Use the
ray.train.torch.prepare_data_loader()utility to set up the DataLoader for distributed training.
You build a LightningDataModule from PyTorch Dataset and DataLoader objects, so the same approach applies.
To use your Hugging Face Dataset with Ray Data, do the following:
Convert your Hugging Face Dataset to a Ray Dataset. For instructions, see Ray Data for Hugging Face.
Pass the Ray Dataset to
TorchTrainerthrough thedatasetsargument.Inside your
train_loop_per_worker, access the sharded dataset throughray.train.get_dataset_shard().Create an iterable dataset through
ray.data.DataIterator.iter_torch_batches().Pass the iterable dataset to
transformers.Trainerwhen you initialize it.Wrap your Transformers
Trainerwith theray.train.huggingface.transformers.prepare_trainer()utility.
To use the Hugging Face Dataset without Ray Data, do the following:
Instantiate the Hugging Face Dataset directly in the
train_loop_per_worker.Pass the Hugging Face Dataset into
transformers.Trainerduring initialization.
Tip
When you use PyTorch or Hugging Face Datasets directly without Ray Data, instantiate your Dataset inside train_loop_per_worker. If you instantiate the Dataset outside train_loop_per_worker and pass it in through global scope, it can cause errors because the Dataset isn’t serializable.
Note
When you use a PyTorch DataLoader with more than one worker, set the process start method to forkserver or spawn. Forking Ray actors and tasks is an anti-pattern that can lead to unexpected issues such as deadlocks.
data_loader = DataLoader(
    dataset,
    num_workers=2,
    multiprocessing_context=multiprocessing.get_context("forkserver"),
    ...
)
Split datasets#
By default, Ray Train splits all datasets across workers with Dataset.streaming_split. Each worker sees a disjoint subset of the data instead of iterating over the entire dataset.
To customize which datasets Ray Train splits, pass a DataConfig to the trainer constructor.
For example, to split only the training dataset, do the following:
import ray
from ray import train
from ray.train import ScalingConfig
from ray.train.torch import TorchTrainer

ds = ray.data.read_text(
    "s3://anonymous@ray-example-data/sms_spam_collection_subset.txt"
)
train_ds, val_ds = ds.train_test_split(0.3)

def train_loop_per_worker():
    # Get the sharded training dataset
    train_ds = train.get_dataset_shard("train")
    for _ in range(2):
        for batch in train_ds.iter_batches(batch_size=128):
            print("Do some training on batch", batch)

    # Get the unsharded full validation dataset
    val_ds = train.get_dataset_shard("val")
    for _ in range(2):
        for batch in val_ds.iter_batches(batch_size=128):
            print("Do some evaluation on batch", batch)

my_trainer = TorchTrainer(
    train_loop_per_worker,
    scaling_config=ScalingConfig(num_workers=2),
    datasets={"train": train_ds, "val": val_ds},
    dataset_config=ray.train.DataConfig(
        datasets_to_split=["train"],
    ),
)
my_trainer.fit()
Advanced: Full customization#
For use cases that the default configuration class doesn’t cover, you can fully customize how Ray Train splits your input datasets. Define a custom DataConfig class, which is a developer API. The DataConfig class is responsible for shared setup and for splitting data across nodes.
# Note that this example class is doing the same thing as the basic DataConfig
# implementation included with Ray Train.
from typing import Optional, Dict, List

import ray
from ray import train
from ray.train.torch import TorchTrainer
from ray.train import DataConfig, ScalingConfig
from ray.data import Dataset, DataIterator, NodeIdStr
from ray.actor import ActorHandle

ds = ray.data.read_text(
    "s3://anonymous@ray-example-data/sms_spam_collection_subset.txt"
)

def train_loop_per_worker():
    # Get an iterator to the dataset we passed in below.
    it = train.get_dataset_shard("train")
    for _ in range(2):
        for batch in it.iter_batches(batch_size=128):
            print("Do some training on batch", batch)


class MyCustomDataConfig(DataConfig):
    def configure(
        self,
        datasets: Dict[str, Dataset],
        world_size: int,
        worker_handles: Optional[List[ActorHandle]],
        worker_node_ids: Optional[List[NodeIdStr]],
        **kwargs,
    ) -> List[Dict[str, DataIterator]]:
        assert len(datasets) == 1, "This example only handles the simple case"

        # Configure Ray Data for ingest.
        ctx = ray.data.DataContext.get_current()
        ctx.execution_options = DataConfig.default_ingest_options()

        # Split the stream into shards.
        iterator_shards = datasets["train"].streaming_split(
            world_size, equal=True, locality_hints=worker_node_ids
        )

        # Return the assigned iterators for each worker.
        return [{"train": it} for it in iterator_shards]


my_trainer = TorchTrainer(
    train_loop_per_worker,
    scaling_config=ScalingConfig(num_workers=2),
    datasets={"train": ds},
    dataset_config=MyCustomDataConfig(),
)
my_trainer.fit()
The subclass must be serializable because Ray Train copies it from the driver script to the driving actor of the trainer. Ray Train calls its configure method on the main actor of the trainer group to create the data iterators for each worker.
You can use DataConfig for any shared setup that has to happen before the workers start iterating over data. The setup runs at the start of each trainer run.
Shuffle data randomly#
Depending on the model you’re training, randomly shuffling data each epoch can be important for model quality.
Ray Data provides multiple options for random shuffling. For details, see Shuffling data.
Enable reproducibility#
When you develop models or tune their hyperparameters, reproducible data ingest is important so that data ingest doesn’t affect model quality. To enable reproducibility, follow these three steps.
Step 1: Enable deterministic execution#
Enable deterministic execution in Ray Datasets by setting the preserve_order flag in the DataContext.
import ray

# Preserve ordering in Ray Datasets for reproducibility.
ctx = ray.data.DataContext.get_current()
ctx.execution_options.preserve_order = True

ds = ray.data.read_text(
    "s3://anonymous@ray-example-data/sms_spam_collection_subset.txt"
)
Step 2: Set a seed for shuffling#
Set a seed for any shuffling operations with the following arguments:
seedargument torandom_shuffleseedargument torandomize_block_orderlocal_shuffle_seedargument toiter_batches
Step 3: Follow your framework’s best practices#
Follow your training framework’s best practices for reproducibility. For example, see the PyTorch reproducibility guide.
Preprocess structured data#
Note
This section covers tabular or structured data. To preprocess unstructured data, use Ray Data operations such as map_batches. For details, see the Ray Data Working with PyTorch guide.
For tabular data, use Ray Data preprocessors, which implement common data preprocessing operations. To use them with Ray Train trainers, apply them to the dataset before you pass it to a trainer. The following example scales some columns, concatenates the results, and saves the fitted preprocessor with the training run:
import base64
import numpy as np
from tempfile import TemporaryDirectory

import ray
from ray import train
from ray.train import Checkpoint, ScalingConfig
from ray.train.torch import TorchTrainer
from ray.data.preprocessors import Concatenator, StandardScaler

dataset = ray.data.read_csv("s3://anonymous@air-example-data/breast_cancer.csv")

# Create preprocessors to scale some columns and concatenate the results.
scaler = StandardScaler(columns=["mean radius", "mean texture"])
columns_to_concatenate = dataset.columns()
columns_to_concatenate.remove("target")
concatenator = Concatenator(columns=columns_to_concatenate, dtype=np.float32)

# Compute dataset statistics and get transformed datasets. Note that the
# fit call is executed immediately, but the transformation is lazy.
dataset = scaler.fit_transform(dataset)
dataset = concatenator.fit_transform(dataset)

def train_loop_per_worker():
    context = train.get_context()
    print(context.get_metadata())  # prints {"preprocessor_pkl": ...}

    # Get an iterator to the dataset we passed in below.
    it = train.get_dataset_shard("train")
    for _ in range(2):
        # Prefetch 10 batches at a time.
        for batch in it.iter_batches(batch_size=128, prefetch_batches=10):
            print("Do some training on batch", batch)

    # Save a checkpoint.
    with TemporaryDirectory() as temp_dir:
        train.report(
            {"score": 2.0},
            checkpoint=Checkpoint.from_directory(temp_dir),
        )

# Serialize the preprocessor. Since serialize() returns bytes,
# convert to base64 string for JSON compatibility.
serialized_preprocessor = base64.b64encode(scaler.serialize()).decode("ascii")

my_trainer = TorchTrainer(
    train_loop_per_worker,
    scaling_config=ScalingConfig(num_workers=2),
    datasets={"train": dataset},
    metadata={"preprocessor_pkl": serialized_preprocessor},
)

# Get the fitted preprocessor back from the result metadata.
metadata = my_trainer.fit().checkpoint.get_metadata()
# Decode from base64 before deserializing
serialized_data = base64.b64decode(metadata["preprocessor_pkl"])
print(StandardScaler.deserialize(serialized_data))
This example persists the fitted preprocessor with the Trainer(metadata={...}) constructor argument. This argument specifies a dict that’s available from TrainContext.get_metadata(), and from checkpoint.get_metadata() for checkpoints that the trainer saves. With this metadata, you can recreate the fitted preprocessor for inference.
Debug data loading bottlenecks#
When you diagnose bottlenecks that slow training throughput, first find out whether training ever stalls to wait for the next data batch. Ray Train’s dashboard builds on Ray Data’s per-stage iterator metrics to answer that question. The Data Ingestion row shows whether data loading is stalling training, then narrows down which stage is responsible and whether rank stragglers are the cause.
To view these panels, run Ray 2.58 or later and set up Prometheus and Grafana for your cluster, as described in Embed Grafana visualizations into Ray dashboard. Ray then provisions a Grafana dashboard titled Train Dashboard. Open it from Grafana’s dashboard list and find the Data Ingestion section.
To identify data loading bottlenecks with these panels, follow these steps.
Step 1: Is training stalling on data loading?#
Check Max Exposed Data Loading Time. This panel reports the per-batch data loading time that the training loop is blocked on. It takes the maximum across ranks, so it reflects the slowest rank.
Ray Data prefetches batches on background threads while your training loop computes on the current batch. Data loading work that finishes before the training loop requests the next batch is fully hidden and costs you nothing. This panel measures only the part that isn’t hidden, which stalls your training.
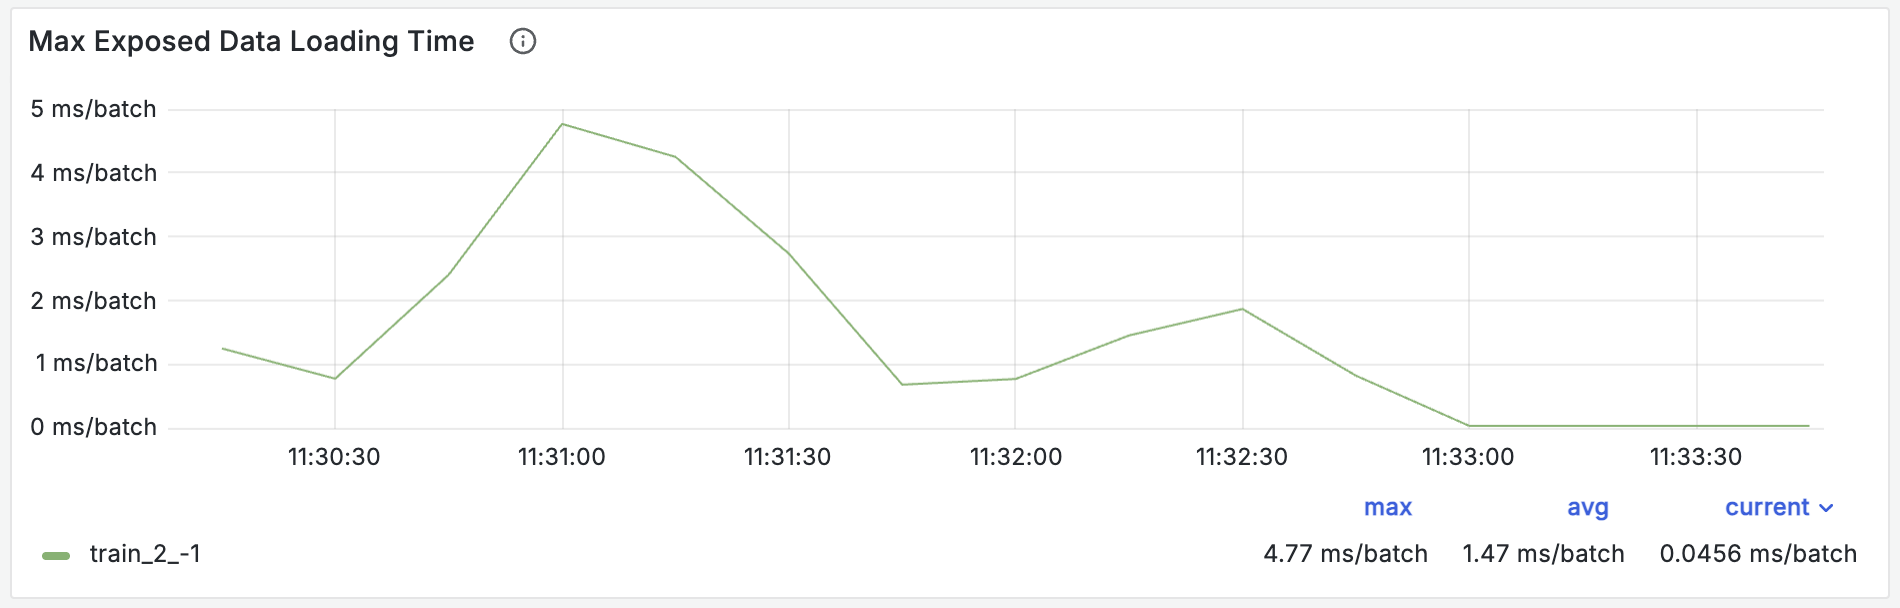
Max Exposed Data Loading Time for a collate-heavy run. The values are non-zero, so training is stalling on data loading and it’s worth continuing to step 2.#
The value is 0. Data loading keeps up with training, and your workload isn’t data loading bound. The time spent in the individual loading stages is hidden behind training, so tuning the ingest pipeline gains you nothing. Look elsewhere for the bottleneck.
The value is non-zero. The training loop is blocking on batches, and every millisecond shown here is a millisecond your accelerators sit idle. Continue to step 2.
To confirm a non-zero reading, check GPU utilization in the GPU Usage panel of the same dashboard. A training loop whose accelerators stay fed holds utilization high and steady. A loop that stalls on data loading shows the opposite pattern. Utilization collapses every time the loop runs dry waiting for the next batch and recovers once the batch arrives, so the chart swings continuously instead of settling. Unstable GPU utilization is often the first symptom you notice, and exposed data loading time explains it. A PyTorch profiler trace shows the same pattern at finer granularity, as gaps between kernel launches while the loop waits.
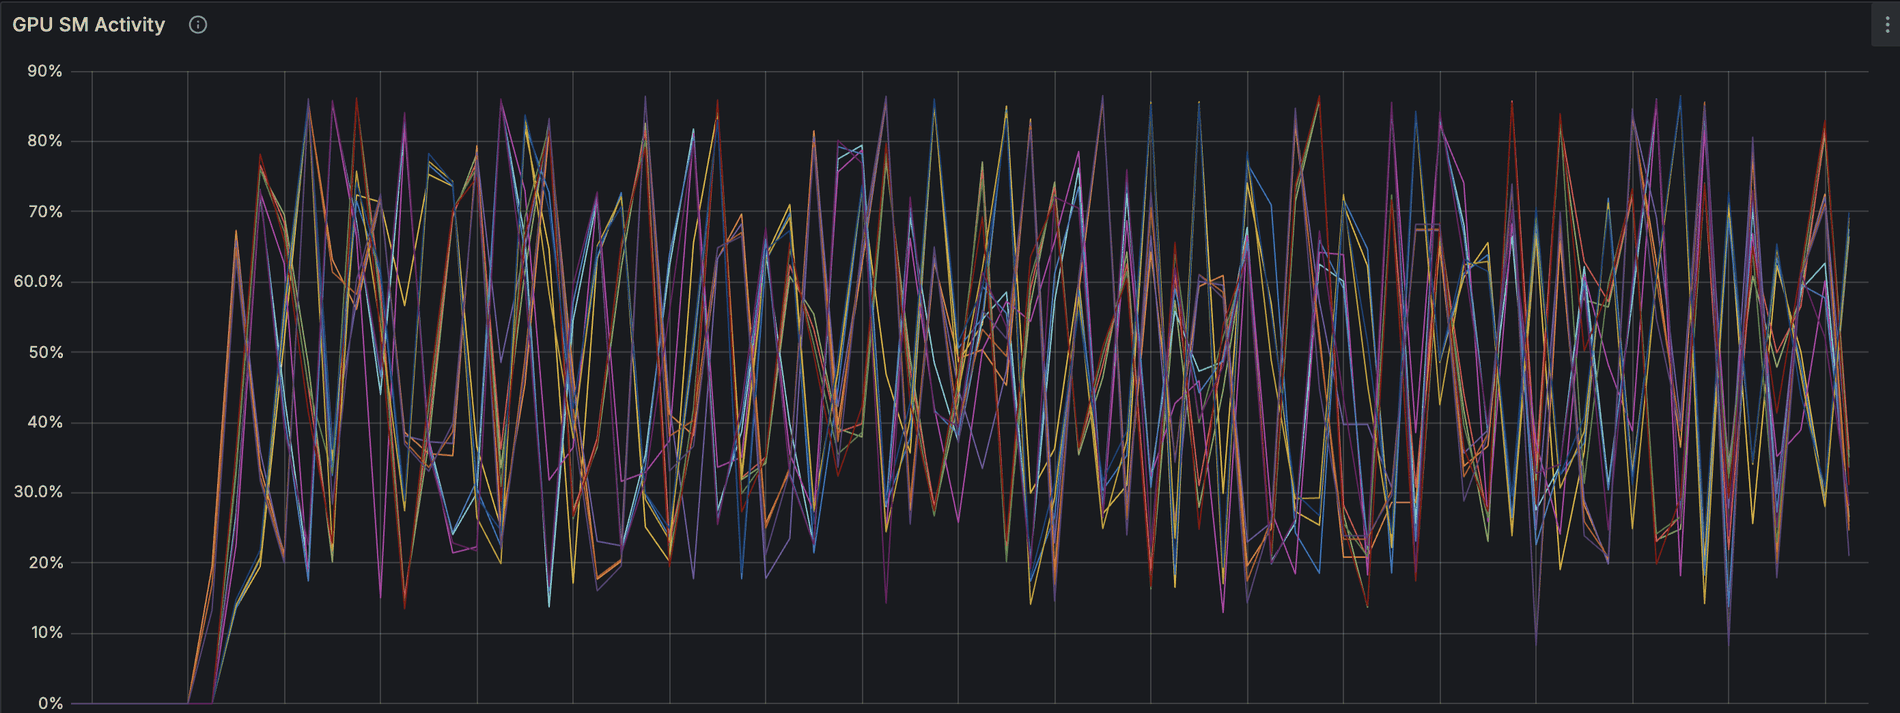
GPU utilization on a run bottlenecked by data loading. Every rank swings between roughly 10% and 85% and never holds a plateau, because the training loop repeatedly runs dry waiting for the next batch.#
Step 2: Which data loading stage is responsible?#
Check Percentage Data Loading Breakdown by Stage. This stacked chart shows the share of per-batch data loading time spent in each stage of the iter_batches pipeline, in the order they run:
Stage |
What it covers |
|---|---|
Production Wait |
Waiting for the upstream Ray Data pipeline to produce the next block. Time in this stage points at the data pipeline rather than at the training worker. |
Data Transfer |
Resolving and transferring blocks to the training worker, including cross-node object store transfers. |
Batching |
Building batches out of blocks, including slicing and local shuffle buffer operations. |
Format |
Converting blocks to the requested batch format, such as NumPy or pandas. |
Collate |
Running your |
Finalize |
Finalizing the batch. For GPU training, this is the host-to-device transfer. |
Look for the stage with the largest share of data loading time. A large Production Wait percentage means the upstream Ray Data pipeline can’t produce data fast enough. A large percentage in any other stage means the bottleneck is last-mile batch preparation on the training worker itself.
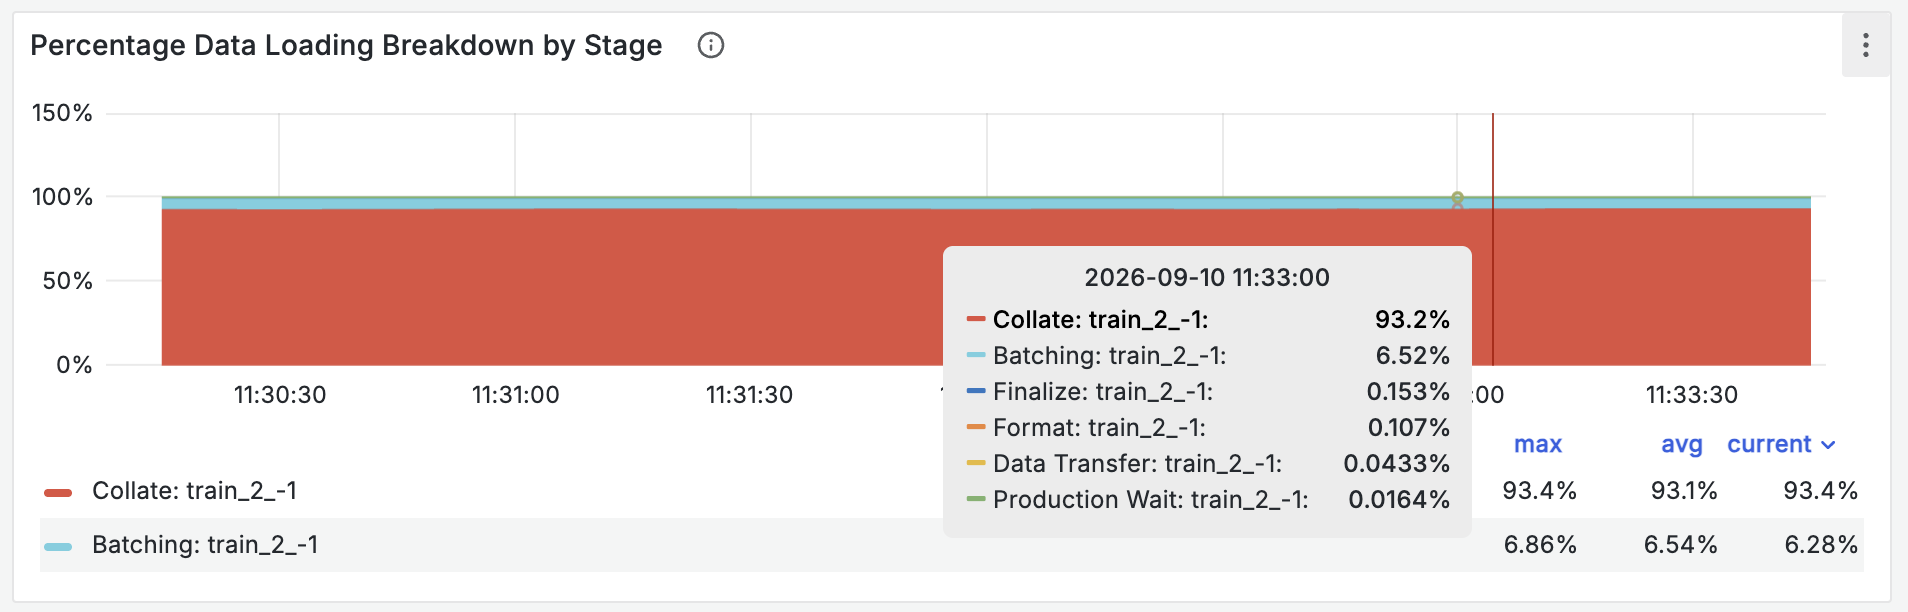
Percentage Data Loading Breakdown by Stage for the same run. Collate accounts for roughly 93% of data loading time and Batching for most of the rest, so the bottleneck is on the training worker rather than upstream.#
Note
This panel breaks down total data loading time, including the portion that pipelining hides behind training, and it always adds up to 100%. Read it only after step 1 shows a non-zero exposed time. Otherwise, none of the stages contribute to a training stall.
Step 3: Is the stage systemically slow, or is one rank straggling?#
Every stage has a matching per-rank panel: Production Wait Time by Rank, Data Transfer Time by Rank, Batching Time by Rank, Format Time by Rank, Collate Time by Rank, and Finalize Time by Rank. Open the one for the stage that step 2 pointed at.
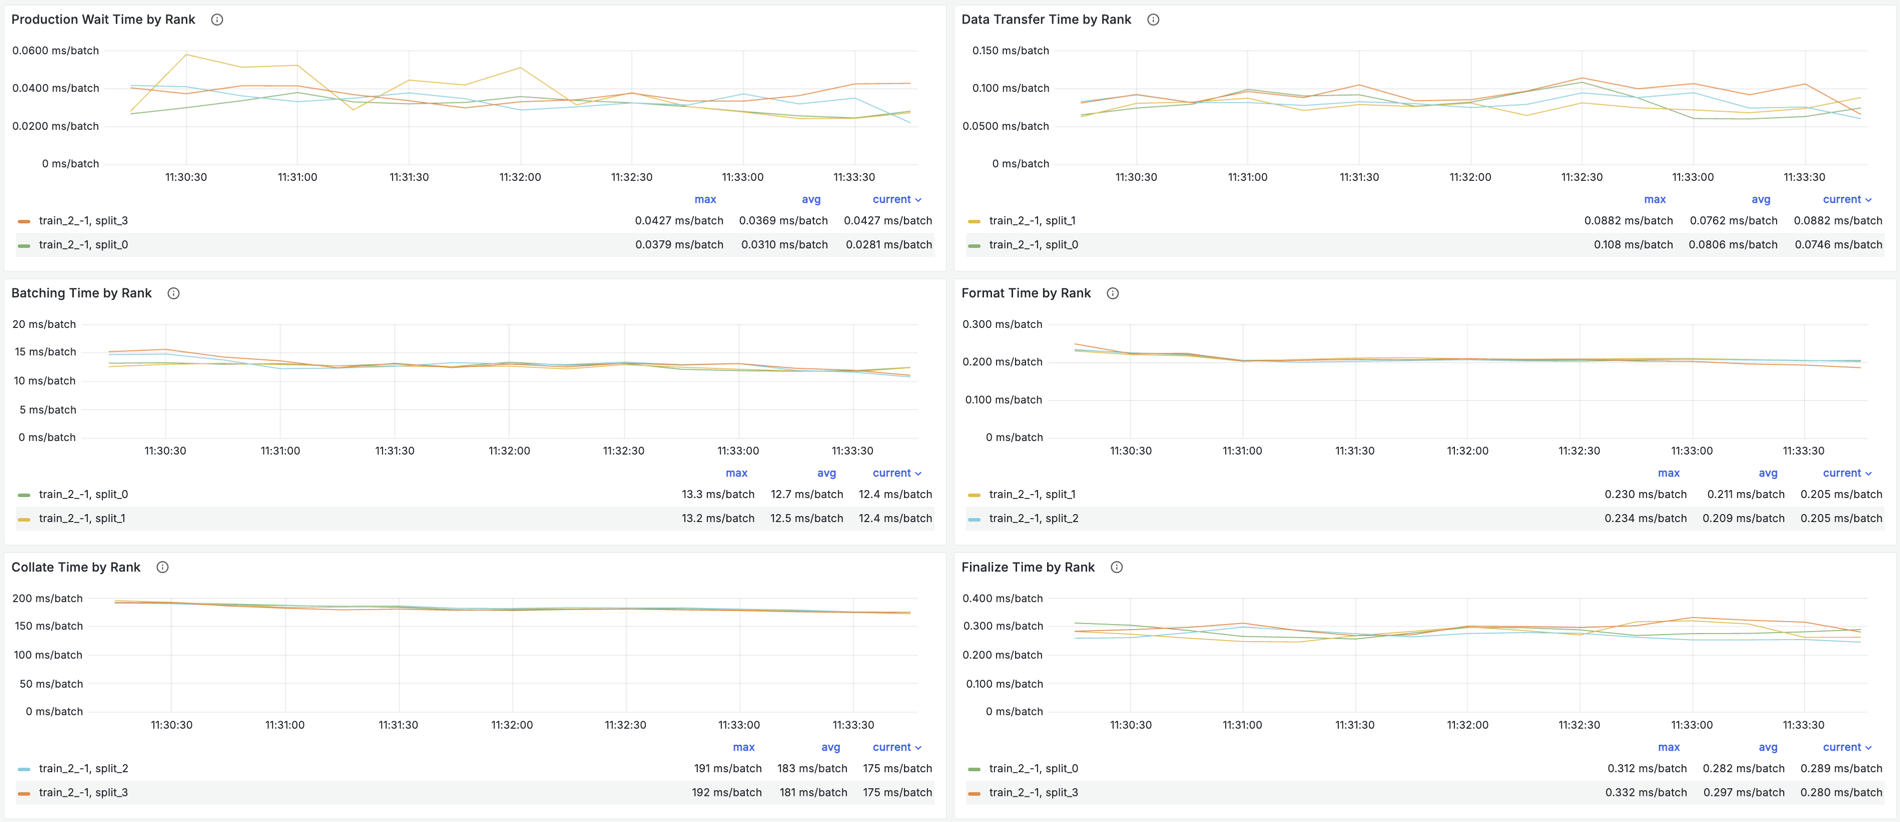
The six per-rank stage panels. Collate time is high but nearly identical on every rank, at roughly 180 ms per batch, which points at a systemically slow stage rather than a straggler.#
Uniformly high across all ranks. The stage is systemically slow, and the fixes in Performance tips apply to the run as a whole.
One rank far above the rest. That rank is a straggler. Because distributed training synchronizes across ranks on every step, a single slow rank holds back the entire run, so a straggler costs you much more than its share of the work. Common causes are poor data locality, where blocks are consistently fetched from a remote node, and a hot node where the training worker competes with Ray Data tasks for CPU.
Monitor ingest throughput#
Two more panels sit alongside the drill-down as general health metrics rather than as steps in it:
Data Ingest Throughput by Rank: rows per second each rank consumes from its data loader. Use it to learn the steady-state ingest rate of a healthy run, so that you can spot drops and imbalance across ranks later.
Data Production Throughput: rows per second the Ray Data pipeline delivers to the training workers. This panel reports data only for datasets that Ray Train splits across workers. The
datasets_to_splitargument ofDataConfigcontrols which datasets those are, so datasets you exclude from splitting show nothing here.
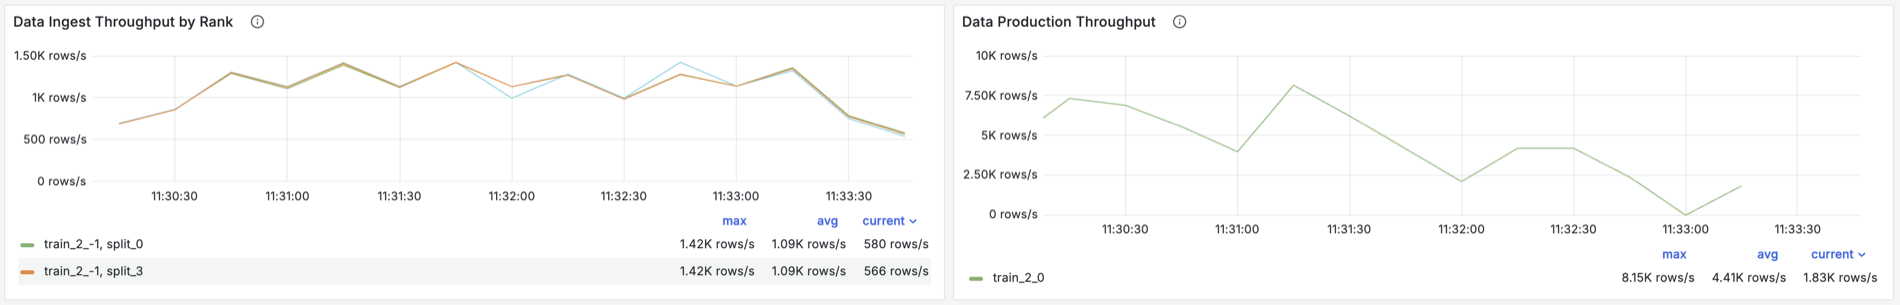
Data Ingest Throughput by Rank and Data Production Throughput for the same run. Aggregate ingest across the four ranks tracks production closely, at roughly 4.4K rows per second, so production and consumption are balanced.#
Choose a fix#
The following table maps each drill-down result to the performance tips that address it.
What the drill-down showed |
Where to look next |
|---|---|
Collate dominates the breakdown |
Avoid heavy transformation in collate_fn and Advanced: Scaling out expensive collate functions |
Data Transfer or Format dominates the breakdown |
|
Production Wait dominates the breakdown |
Add CPU-only nodes to your cluster and Cache the preprocessed dataset |
A single rank straggles |
|
Batching dominates and you use a large local shuffle buffer |
For lower-level, per-operator timings that these panels don’t cover, see the Ray Data dashboard and Ray Data stats.
Performance tips#
Prefetch batches#
When you iterate over a dataset for training, you can increase prefetch_batches in iter_batches or iter_torch_batches to improve performance. While training runs on the current batch, Ray Data launches background threads to fetch and process the next N batches.
Prefetching can help if training is bottlenecked on cross-node data transfer or on last-mile preprocessing, such as converting batches to tensors or running collate_fn. However, a higher prefetch_batches value holds more data in heap memory. The default prefetch_batches value is 1.
For example, the following code prefetches 10 batches at a time for each training worker:
import ray
from ray import train
from ray.train import ScalingConfig
from ray.train.torch import TorchTrainer

ds = ray.data.read_text(
    "s3://anonymous@ray-example-data/sms_spam_collection_subset.txt"
)

def train_loop_per_worker():
    # Get an iterator to the dataset we passed in below.
    it = train.get_dataset_shard("train")
    for _ in range(2):
        # Prefetch 10 batches at a time.
        for batch in it.iter_batches(batch_size=128, prefetch_batches=10):
            print("Do some training on batch", batch)

my_trainer = TorchTrainer(
    train_loop_per_worker,
    scaling_config=ScalingConfig(num_workers=2),
    datasets={"train": ds},
)
my_trainer.fit()
Avoid heavy transformation in collate_fn#
With the collate_fn parameter in iter_batches or iter_torch_batches, you can transform data before feeding it to the model. This operation runs locally in the training workers. Avoid adding a heavy transformation in this function because it might become the bottleneck. Instead, apply the transformation with map or map_batches before you pass the dataset to the trainer. When your expensive transformation requires batch_size as input, such as text tokenization, scale it out to Ray Data for better performance.
Cache the preprocessed dataset#
If your preprocessed dataset is small enough to fit in Ray object store memory, materialize it in Ray’s built-in object store by calling materialize() on it. By default, object store memory is 30% of total cluster RAM. This method tells Ray Data to compute the entire preprocessed dataset and pin it in Ray object store memory. As a result, the preprocessing operations don’t need to rerun when you iterate over the dataset repeatedly. However, if the preprocessed data is too large to fit in Ray object store memory, this approach greatly decreases performance, because data has to be spilled to disk and read back.
Place transformations that you want to run every epoch, such as randomization, after the materialize() call.
from typing import Dict
import numpy as np
import ray

# Load the data.
train_ds = ray.data.read_parquet("s3://anonymous@ray-example-data/iris.parquet")

# Define a preprocessing function.
def normalize_length(batch: Dict[str, np.ndarray]) -> Dict[str, np.ndarray]:
    new_col = batch["sepal.length"] / np.max(batch["sepal.length"])
    batch["normalized.sepal.length"] = new_col
    del batch["sepal.length"]
    return batch

# Preprocess the data. Transformations that are made before the materialize call
# below are only run once.
train_ds = train_ds.map_batches(normalize_length, batch_size="auto")

# Materialize the dataset in object store memory.
# Only do this if train_ds is small enough to fit in object store memory.
train_ds = train_ds.materialize()

# Dummy augmentation transform.
def augment_data(batch):
    return batch

# Add per-epoch preprocessing. Transformations that you want to run per-epoch, such
# as data augmentation or randomization, should go after the materialize call.
train_ds = train_ds.map_batches(augment_data, batch_size="auto")

# Pass train_ds to the Trainer
Add CPU-only nodes to your cluster#
If expensive CPU preprocessing bottlenecks GPU training and the preprocessed dataset is too large to fit in object store memory, materializing the dataset doesn’t work. In this case, add more CPU-only nodes to your cluster. Ray supports heterogeneous resources natively, so Ray Data automatically scales out CPU-only preprocessing tasks to the CPU-only nodes, which keeps the GPUs more saturated.
Adding CPU-only nodes can help in two ways:
More CPU cores parallelize preprocessing further. This helps when CPU compute time is the bottleneck.
More object store memory gives Ray Data room to buffer more data between the preprocessing and training stages, and makes it possible to cache the preprocessed dataset. This helps when memory is the bottleneck.
Isolate Ray Data worker processes from training nodes#
When training workers themselves run CPU-heavy or RAM-heavy operations, such as storing large local shuffle buffers or running expensive collate functions, you might want to keep Ray Data CPU tasks off the training worker nodes. Launching more Ray Data processes would oversubscribe those nodes. Instead, run the Ray Data tasks on a separate set of CPU nodes in your heterogeneous cluster, such as a cluster with four GPU training nodes and four CPU-only nodes.
One workaround is to force full-node exclusion by reserving all CPUs for each training worker with resources_per_worker={"CPU": node_cpus // num_gpus_per_node, "GPU": 1} in ScalingConfig. This method is fragile because it’s tied to node shapes. Ray Data also doesn’t properly exclude other resources such as object store memory, because the typical configuration takes up only logical CPUs and GPUs.
Instead, use subclusters to pin the training dataset to CPU-only nodes. This approach correctly scopes the memory budget to only the nodes where data tasks can run. To set it up, add labels to your worker node configurations and set label_selector in two places:
import ray
from ray.data import ExecutionOptions
from ray.train import DataConfig
from ray.train.torch import TorchTrainer

# (1) Pin construction-time tasks (schema inference, file listing).
ctx = ray.data.DataContext.get_current().copy()
ctx.execution_options.label_selector = {"ray-subcluster": "data"}
with ray.data.DataContext.current(ctx):
    train_dataset = ray.data.read_parquet(...)

# (2) Pin per-worker ingest. Train replaces ds.context options
# wholesale, so the selector must be restated here.
trainer = TorchTrainer(
    ...,
    datasets={"train": train_dataset},
    dataset_config=DataConfig(
        datasets_to_split=["train"],
        execution_options={
            "train": ExecutionOptions(
                label_selector={"ray-subcluster": "data"}
            ),
        },
    ),
)
Tip
Before you isolate Ray Data tasks from training nodes, try offloading the heavy work from training workers to the data pipeline. Scale out expensive collation, and use map_batches-based shuffling instead of large local shuffle buffers. These changes reduce CPU pressure on training workers and often eliminate the need for node isolation.
For details on tuning Ray Data, see Advanced: Performance tips and tuning.
More data ingest guides#
Weighted dataset mixing: combine multiple datasets with target row ratios for training.
Scaling out expensive collate functions: scale out expensive collation functions to Ray Data.