Out-of-memory prevention#
If application tasks or actors consume a large amount of heap space, the node can run out of memory (OOM). When that happens, the operating system starts killing worker or raylet processes, which disrupts the application. OOM might also stall metrics. If it happens on the head node, it might stall the dashboard or other control processes and make the cluster unusable.
This page explains what the memory monitor is, how it works, and how to enable and configure it. To troubleshoot out-of-memory issues, see Debugging out of memory.
What is the memory monitor?#
The memory monitor is a component that runs within the raylet process on each node. It monitors memory usage, which includes the worker heap, the object store, and the raylet, as described in memory management. If the combined usage exceeds a configurable threshold, the raylet kills a task or actor process to free up memory and prevent Ray from failing.
It’s available on Linux and tested with Ray running inside a container that uses cgroup v1 or v2. If you encounter issues when running the memory monitor outside a container, file an issue or post a question.
What to expect?#
The default memory monitoring system protects the Ray node from node death caused by memory contention and OOM. Compared with the Linux OOM killer, it also aims to preserve as much application progress as possible by killing workers based on the time since the task started executing. However, the default memory monitoring system makes no guarantees.
As of Ray 2.56, when you enable resource isolation, the memory monitoring system provides the following:
Zero kernel OOM kills when you enable resource isolation and configure system-reserved memory to cover the memory footprint of critical Ray system processes and other system overhead. The critical Ray system processes are the raylet, the GCS, and the agents. This behavior is work-preserving.
Zero Ray OOM kills under the preceding configuration when tasks and actors specify accurate logical memory requests.
Zero node deaths caused by memory contention when you enable resource isolation and configure system-reserved memory correctly.
To enable resource isolation, see How to enable cgroup v2 for resource isolation.
How do I disable the memory monitor?#
Ray enables the memory monitor by default. You can disable it only when resource isolation is disabled. To disable the memory monitor when resource isolation is off, set the environment variable RAY_memory_monitor_refresh_ms to zero when you start Ray, as in RAY_memory_monitor_refresh_ms=0 ray start ....
How do I configure the memory monitor?#
Default memory monitor configuration:
The following environment variables control the memory monitor:
RAY_memory_monitor_refresh_ms (int, defaults to 250)is the interval at which the memory monitor checks memory usage and kills tasks or actors if needed. A value of 0 disables task killing. The memory monitor selects and kills one task at a time and waits for it to be killed before it chooses another one, regardless of how frequently the memory monitor runs.RAY_memory_usage_threshold (float, defaults to 0.95)is the memory usage threshold, as a fraction of the node’s memory capacity. If memory usage exceeds this fraction, the memory monitor starts killing processes to free up memory. The value ranges from [0, 1].
Resource isolation memory monitor configuration:
When resource isolation is enabled, the following flag, which you pass to ray start or ray.init, controls the memory monitor:
--system-reserved-memorysets the amount of memory reserved for critical Ray system processes and other system processes outside Ray’s userspace. By default, this value is 10% of the system’s total memory, bounded by a minimum of 500 MiB and a maximum of 10 GiB. The memory monitor enforces that the workload processes’ memory footprint doesn’t exceedtotal_memory - system_reserved_memorybytes.
Using the memory monitor#
Retry policy#
When the memory monitor kills a task or actor, it’s retried with exponential backoff. The retry delay has a cap of 60 seconds. If the memory monitor kills tasks, it retries them infinitely and doesn’t respect max_retries, unless you set max_retries to 0. When max_retries is 0, the task isn’t retried. If the memory monitor kills actors, it doesn’t recreate the actor infinitely. It respects max_restarts, which is 0 by default.
Worker killing policy#
Worker killing policy since Ray 2.56#
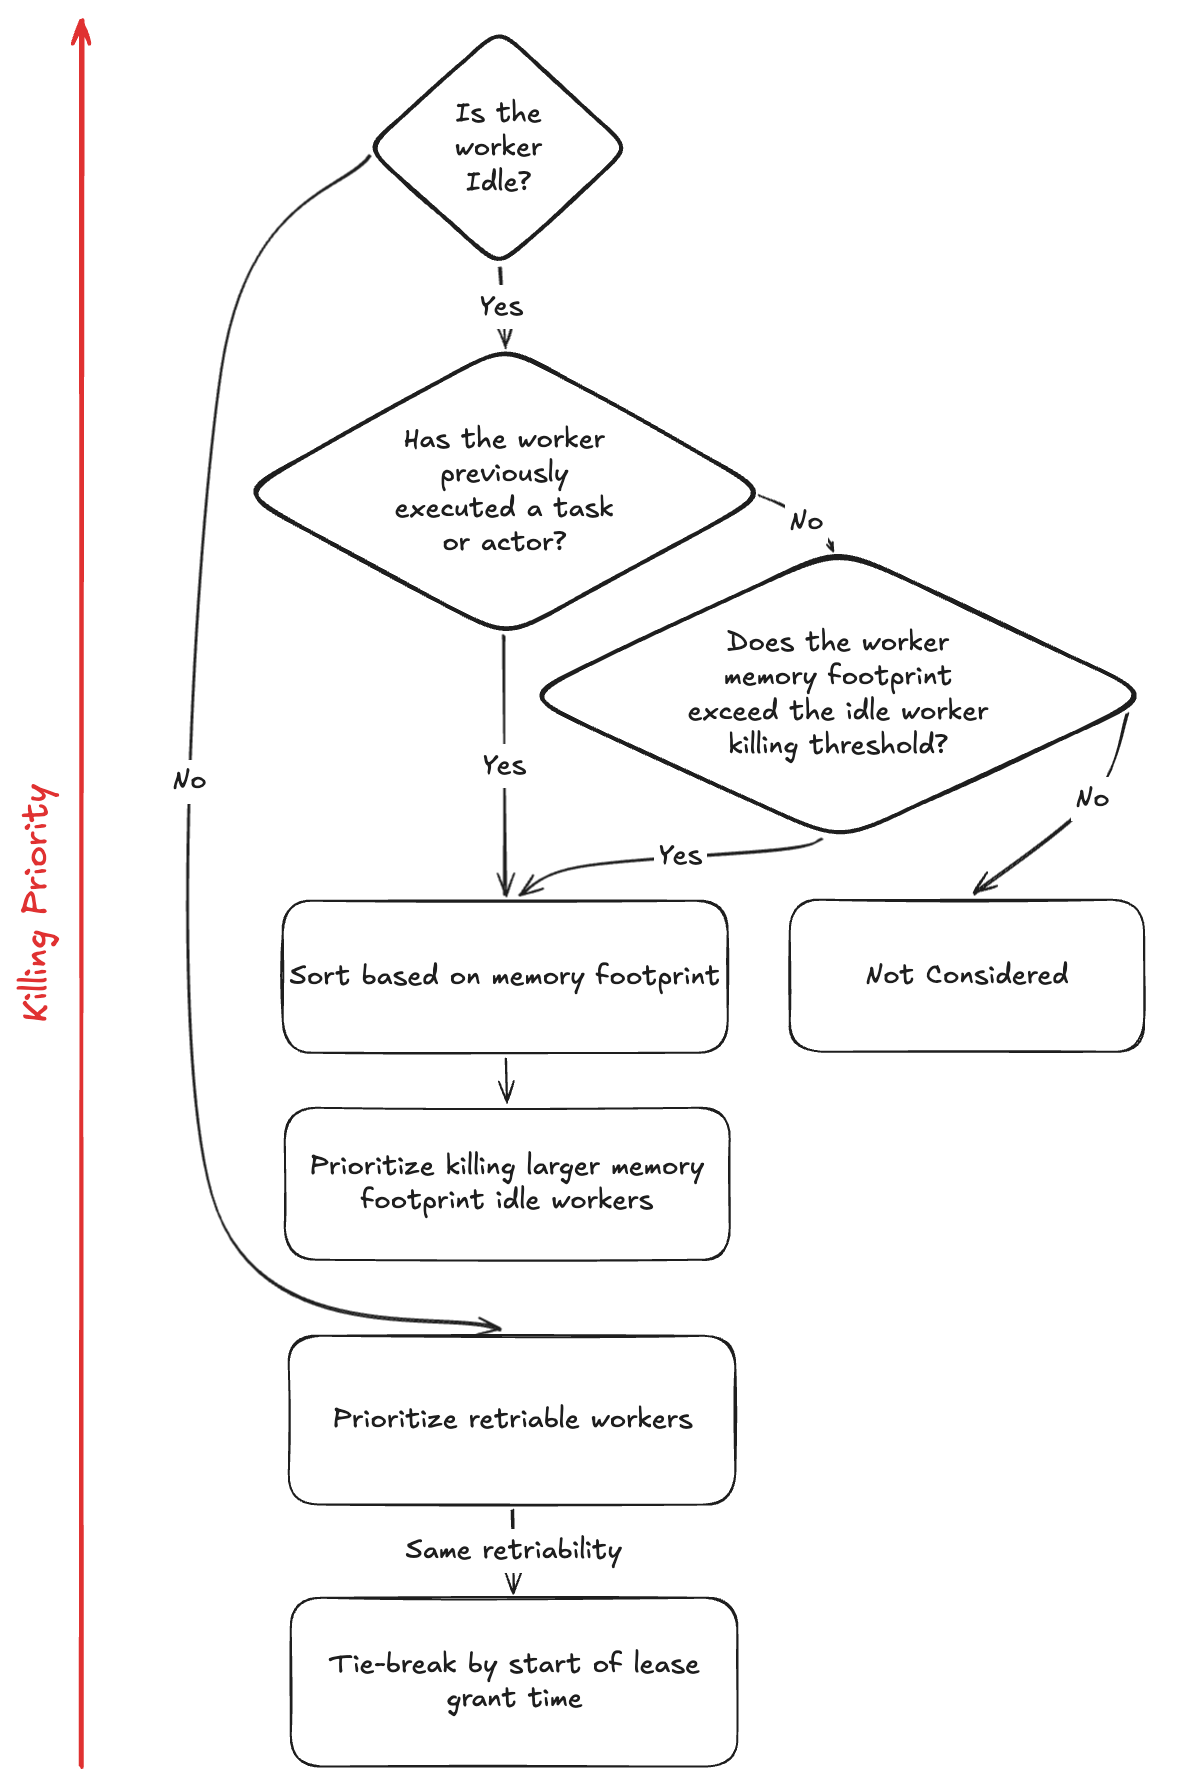
As the preceding diagram shows, the worker killing policy prioritizes idle workers over active workers when it selects workers to kill.
Idle worker policy:
The memory monitor always considers all workers that have previously executed tasks or actors for killing, regardless of the idle-worker killing memory threshold. It considers workers that have never executed any tasks or actors, called cold-start idle workers, for killing only if their memory footprint exceeds the idle-worker killing memory threshold. Cold-start idle workers should have a small memory footprint. In the unlikely case that the OOM logs show the policy selecting active workers over idle workers while a large idle-worker memory footprint remains, the dependencies that new processes in Ray’s userspace inherit at startup are likely too expensive. In that case, consider reducing the memory footprint of new processes in Ray’s userspace, or lowering the idle-worker killing memory threshold with the environment variable
RAY_idle_worker_killing_memory_threshold_bytes, which defaults to 1 GiB.Among the workers eligible for killing, the policy selects the worker with the largest memory footprint first.
Active worker policy:
For workers running tasks or actors, called active workers, the policy prioritizes retryable tasks to maximize retry opportunities.
Among active workers with the same retryability, the policy next selects the most recent workers, meaning the ones with the newest granted lease time.
The policy keeps selecting workers until current_memory_usage - total_selected_workers_memory_footprint + kill_buffer <= available_memory_for_workload_processes. In this condition, current_memory_usage is the current memory usage on the node, and total_selected_workers_memory_footprint is the sum of the memory footprints of all workers selected to kill. The kill_buffer is the amount of memory to leave as breathing room between the memory usage and the memory allocated to the workload processes. The available_memory_for_workload_processes is the amount of memory available for the workload processes to use, computed as total_system_memory - system_reserved_memory as described earlier. The kill_buffer defaults to 5% of the total system memory and caps at 3 GiB, which you can configure with RAY_max_kill_memory_buffer_bytes.
To revert to the legacy worker killing policy, set the environment variable RAY_worker_killing_policy_by_group to true before you start Ray.
Legacy worker killing policy#
The memory monitor avoids infinite loops of task retries by ensuring that at least one task can run for each caller on each node. If it can’t ensure this, the workload fails with an OOM error. This is only an issue for tasks, because the memory monitor doesn’t retry actors indefinitely. If the workload fails, see how to address memory issues to adjust the workload so that it passes. For a code example, see the last task example later on this page.
When the policy needs to kill a worker, it first prioritizes retryable workers. A worker is retryable if its task’s max_retries or its actor’s max_restarts isn’t 0. This prioritization minimizes workload failure. Actors aren’t retryable by default, because max_restarts defaults to 0. Therefore, by default, the policy prefers to kill tasks before actors.
When multiple callers have created tasks, the policy picks a task from the caller with the most running tasks. If two callers have the same number of tasks, it picks the caller whose earliest task has a later start time. This rule ensures fairness so that each caller can make progress.
Among tasks that share the same caller, the policy first kills the task that started last.
The following example demonstrates the policy. A script creates two tasks, which in turn create four more tasks each. Each color in the diagram marks a group of tasks that belong to the same caller.

If the node runs out of memory at this point, the policy picks a task from the caller with the most tasks and kills the task from that caller that started last:

If the node still runs out of memory at this point, the process repeats:

Example: Workload fails if the policy kills the caller’s last task
Create an application oom.py that runs a single task that requires more memory than is available. The task retries infinitely because it sets max_retries to -1.
The worker killing policy sees that this task is the caller’s last task. When the policy kills the task, the workload fails, even though the task is set to retry forever.
import ray

@ray.remote(max_retries=0)
def leaks_memory():
    chunks = []
    bits_to_allocate = 8 * 100 * 1024 * 1024  # ~100 MiB
    while True:
        chunks.append([0] * bits_to_allocate)


try:
    ray.get(leaks_memory.remote())
except ray.exceptions.OutOfMemoryError as ex:
    print("task failed with OutOfMemoryError, which is expected")
Set RAY_event_stats_print_interval_ms=1000 to print the worker kill summary every second. By default, Ray prints it every minute.
RAY_event_stats_print_interval_ms=1000 python oom.py

(raylet) node_manager.cc:3040: 1 Workers (tasks / actors) killed due to memory pressure (OOM), 0 Workers crashed due to other reasons at node (ID: 2c82620270df6b9dd7ae2791ef51ee4b5a9d5df9f795986c10dd219c, IP: 172.31.183.172) over the last time period. To see more information about the Workers killed on this node, use `ray logs raylet.out -ip 172.31.183.172`
(raylet)
(raylet) Refer to the documentation on how to address the out of memory issue: https://docs.ray.io/en/latest/ray-core/scheduling/ray-oom-prevention.html. Consider provisioning more memory on this node or reducing task parallelism by requesting more CPUs per task. To adjust the kill threshold, set the environment variable `RAY_memory_usage_threshold` when starting Ray. To disable worker killing, set the environment variable `RAY_memory_monitor_refresh_ms` to zero.
        task failed with OutOfMemoryError, which is expected
        Verify the task was indeed executed twice via ``task_oom_retry``:
Example: Memory monitor prefers to kill a retryable task
First, start Ray and specify the memory threshold.
RAY_memory_usage_threshold=0.4 ray start --head
Create an application two_actors.py that submits two actors. The first actor is retryable and the second isn’t.
from math import ceil
import ray
from ray._private.utils import (
    get_system_memory,
)  # do not use outside of this example as these are private methods.
from ray._private.utils import (
    get_used_memory,
)  # do not use outside of this example as these are private methods.


# estimates the number of bytes to allocate to reach the desired memory usage percentage.
def get_additional_bytes_to_reach_memory_usage_pct(pct: float) -> int:
    used = get_used_memory()
    total = get_system_memory()
    bytes_needed = int(total * pct) - used
    assert (
        bytes_needed > 0
    ), "memory usage is already above the target. Increase the target percentage."
    return bytes_needed


@ray.remote
class MemoryHogger:
    def __init__(self):
        self.allocations = []

    def allocate(self, bytes_to_allocate: float) -> None:
        # divide by 8 as each element in the array occupies 8 bytes
        new_list = [0] * ceil(bytes_to_allocate / 8)
        self.allocations.append(new_list)


first_actor = MemoryHogger.options(
    max_restarts=1, max_task_retries=1, name="first_actor"
).remote()
second_actor = MemoryHogger.options(
    max_restarts=0, max_task_retries=0, name="second_actor"
).remote()

# We want total bytes to exceed 40% threshold to trigger the memory monitor.
allocate_bytes = get_additional_bytes_to_reach_memory_usage_pct(0.5)

first_actor_task = first_actor.allocate.remote(0.9 * allocate_bytes)
second_actor_task = second_actor.allocate.remote(0.1* allocate_bytes)

error_thrown = False
try:
    ray.get(first_actor_task)
except ray.exceptions.OutOfMemoryError as ex:
    error_thrown = True
    print("First started actor, which is retriable, was killed by the memory monitor.")
assert error_thrown

ray.get(second_actor_task)
print("Second started actor, which is not-retriable, finished.")
Run the application to see that the memory monitor kills only the first actor.
$ python two_actors.py

First started actor, which is retriable, was killed by the memory monitor.
Second started actor, which is not-retriable, finished.
Questions or issues?#
You can post questions or issues or feedback through the following channels:
Discussion Board: For questions about Ray usage or feature requests.
GitHub Issues: For bug reports.
Ray Slack: For getting in touch with Ray maintainers.
StackOverflow: Use the [ray] tag for questions about Ray.