Save and load checkpoints#
Save snapshots of training progress with Ray Train Checkpoints.
Use checkpoints for the following:
Fault tolerance: Handle worker process and node failures in a long-running training job, and use preemptible machines. When you enable worker fault tolerance, Ray Train restarts the workers after a failure, and a training function that loads the latest checkpoint resumes from it.
Storing the best-performing model weights: Save your model to persistent storage, and use it for downstream serving or inference.
Distributed checkpointing: Upload model shards from multiple workers in parallel.
Save checkpoints during training#
A Ray Train Checkpoint is a lightweight interface that represents a directory on local or remote storage.
For example, a checkpoint can point to a cloud storage directory such as s3://my-bucket/my-checkpoint-dir. A locally available checkpoint points to a location on the local filesystem, such as /tmp/my-checkpoint-dir.
To save a checkpoint in the training loop, do the following:
Write your model checkpoint to a local directory.
A
Checkpointonly points to a directory, so you decide what it contains.You can use any serialization format.
You can use the checkpoint utilities that training frameworks provide, such as
torch.save,pl.Trainer.save_checkpoint, the Accelerateaccelerator.save_model, the Transformerssave_pretrained, andtf.keras.Model.save.
Create a
Checkpointfrom the directory usingCheckpoint.from_directory.Report the checkpoint to Ray Train using
ray.train.report(metrics, checkpoint=...).This call uploads the checkpoint to persistent storage, if configured. See Configure persistent storage.
After a failure,
ray.train.get_checkpoint()returns the latest reported checkpoint so that the training function can resume from it. See Restore training state from a checkpoint.Ray Train uses the metrics you report alongside the checkpoint to keep track of the best-performing checkpoints.
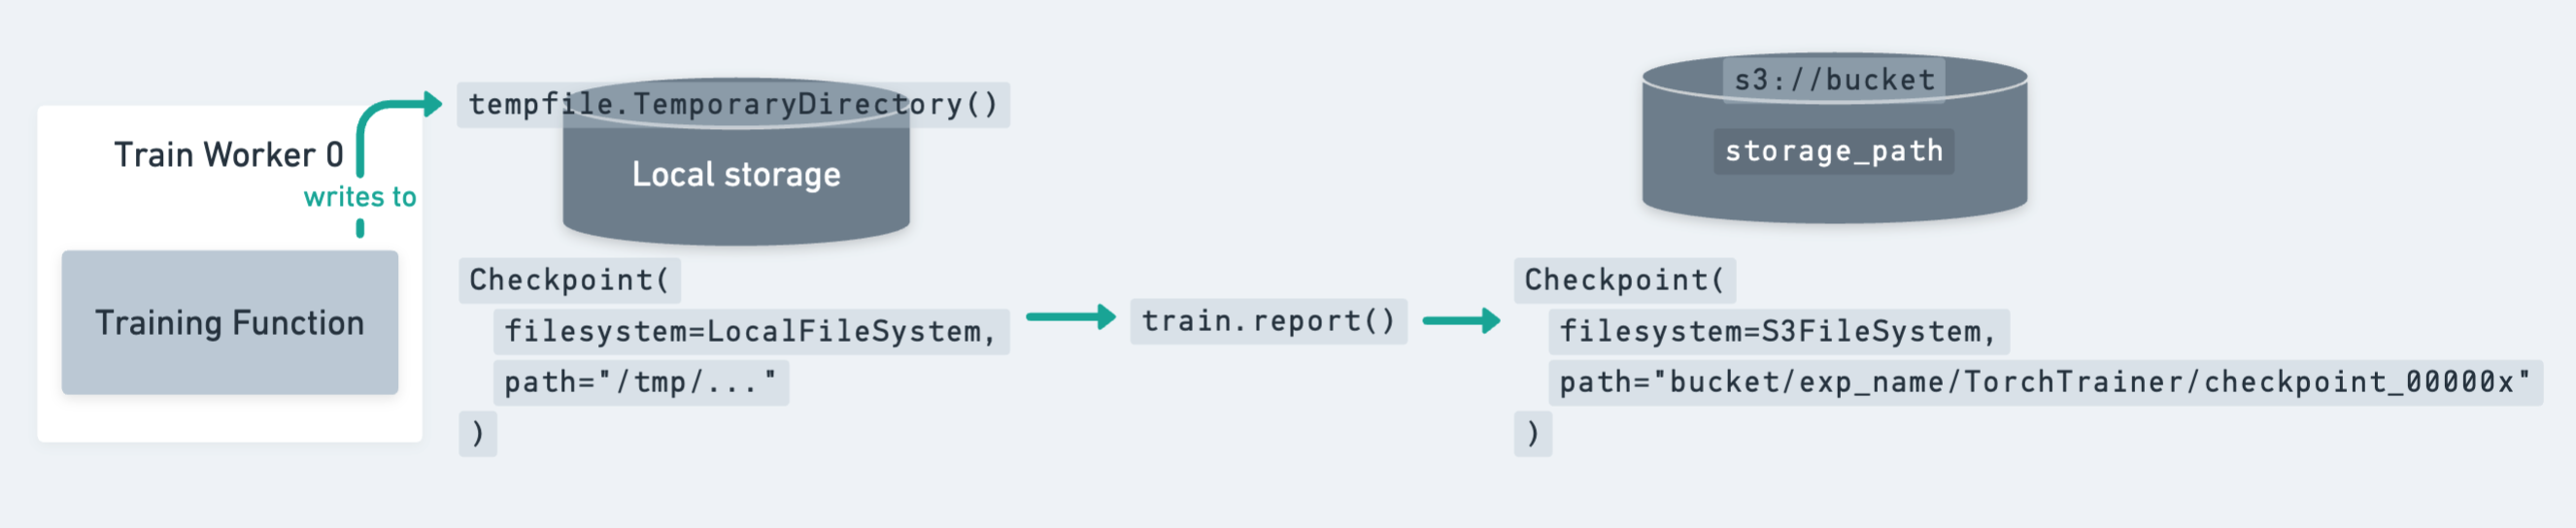
The lifecycle of a Checkpoint, from saving locally
to disk to uploading to persistent storage through train.report.#
As the preceding figure shows, first write the checkpoint to a local temporary directory. Then call train.report, which uploads the checkpoint to its final persistent storage location. After that, you can safely clean up the local temporary directory to free disk space, for example by exiting the tempfile.TemporaryDirectory context.
Tip
In standard DDP training, each worker has a copy of the full model, so save and report a checkpoint from only one worker to prevent redundant uploads.
The following example shows the typical pattern:
import tempfile

from ray import train


def train_fn(config):
    ...

    metrics = {...}
    with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
        checkpoint = None

        # Only the global rank 0 worker saves and reports the checkpoint
        if train.get_context().get_world_rank() == 0:
            ...  # Save checkpoint to temp_checkpoint_dir

            checkpoint = Checkpoint.from_directory(temp_checkpoint_dir)

        train.report(metrics, checkpoint=checkpoint)
With parallel training strategies such as DeepSpeed ZeRO and FSDP, each worker has only a shard of the full training state, so you can save and report a checkpoint from each worker. For an example, see Save checkpoints from multiple workers.
The following examples show how to save checkpoints with different training frameworks:
import os
import tempfile

import numpy as np
import torch
import torch.nn as nn
from torch.optim import Adam

import ray.train.torch
from ray import train
from ray.train import Checkpoint, ScalingConfig
from ray.train.torch import TorchTrainer


def train_func(config):
    n = 100
    # create a toy dataset
    # data   : X - dim = (n, 4)
    # target : Y - dim = (n, 1)
    X = torch.Tensor(np.random.normal(0, 1, size=(n, 4)))
    Y = torch.Tensor(np.random.uniform(0, 1, size=(n, 1)))
    # toy neural network : 1-layer
    # Wrap the model in DDP
    model = ray.train.torch.prepare_model(nn.Linear(4, 1))
    criterion = nn.MSELoss()

    optimizer = Adam(model.parameters(), lr=3e-4)
    for epoch in range(config["num_epochs"]):
        y = model.forward(X)
        loss = criterion(y, Y)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()

        metrics = {"loss": loss.item()}

        with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
            checkpoint = None

            should_checkpoint = epoch % config.get("checkpoint_freq", 1) == 0
            # In standard DDP training, where the model is the same across all ranks,
            # only the global rank 0 worker needs to save and report the checkpoint
            if train.get_context().get_world_rank() == 0 and should_checkpoint:
                torch.save(
                    model.module.state_dict(),  # NOTE: Unwrap the model.
                    os.path.join(temp_checkpoint_dir, "model.pt"),
                )
                checkpoint = Checkpoint.from_directory(temp_checkpoint_dir)

            train.report(metrics, checkpoint=checkpoint)


trainer = TorchTrainer(
    train_func,
    train_loop_config={"num_epochs": 5},
    scaling_config=ScalingConfig(num_workers=2),
)
result = trainer.fit()
Tip
In most cases, unwrap the DDP model before you save it to a checkpoint. model.module.state_dict() is the state dict without the "module." prefix on each key.
Ray Train uses PyTorch Lightning’s Callback interface to report metrics and checkpoints. Ray Train provides a callback implementation that reports on_train_epoch_end.
At the end of each training epoch, the callback does the following:
Collects all the logged metrics from
trainer.callback_metrics.Saves a checkpoint through
trainer.save_checkpoint.Reports to Ray Train through
ray.train.report(metrics, checkpoint).
import lightning.pytorch as pl

from ray import train
from ray.train.lightning import RayTrainReportCallback
from ray.train.torch import TorchTrainer


class MyLightningModule(pl.LightningModule):
    # ...

    def on_validation_epoch_end(self):
        ...
        mean_acc = calculate_accuracy()
        self.log("mean_accuracy", mean_acc, sync_dist=True)


def train_func():
    ...
    model = MyLightningModule(...)
    datamodule = MyLightningDataModule(...)

    trainer = pl.Trainer(
        # ...
        callbacks=[RayTrainReportCallback()]
    )
    trainer.fit(model, datamodule=datamodule)


ray_trainer = TorchTrainer(
    train_func,
    scaling_config=train.ScalingConfig(num_workers=2),
    run_config=train.RunConfig(
        checkpoint_config=train.CheckpointConfig(
            num_to_keep=2,
            checkpoint_score_attribute="mean_accuracy",
            checkpoint_score_order="max",
        ),
    ),
)
You can get the saved checkpoint path from result.checkpoint and result.best_checkpoints.
For more advanced usage, such as reporting at a different frequency or reporting custom checkpoint files, implement your own callback. The following example reports a checkpoint every three epochs:
import os
from tempfile import TemporaryDirectory

from lightning.pytorch.callbacks import Callback

import ray
import ray.train
from ray.train import Checkpoint


class CustomRayTrainReportCallback(Callback):
    def on_train_epoch_end(self, trainer, pl_module):
        should_checkpoint = trainer.current_epoch % 3 == 0

        with TemporaryDirectory() as tmpdir:
            # Fetch metrics from `self.log(..)` in the LightningModule
            metrics = trainer.callback_metrics
            metrics = {k: v.item() for k, v in metrics.items()}

            # Add customized metrics
            metrics["epoch"] = trainer.current_epoch
            metrics["custom_metric"] = 123

            checkpoint = None
            if should_checkpoint:
                # Save model checkpoint file to tmpdir
                ckpt_path = os.path.join(tmpdir, "ckpt.pt")
                trainer.save_checkpoint(ckpt_path, weights_only=False)

                checkpoint = Checkpoint.from_directory(tmpdir)

            # Report to train session
            ray.train.report(metrics=metrics, checkpoint=checkpoint)
            trainer.strategy.barrier()
Ray Train uses the Callback interface of the Hugging Face Transformers Trainer to report metrics and checkpoints.
Option 1: Use Ray Train’s default report callback
Ray Train provides the callback implementation RayTrainReportCallback, which reports whenever the Trainer saves a checkpoint. It collects the latest logged metrics and reports them together with the latest saved checkpoint. To change the checkpointing frequency, set save_strategy and save_steps.
from transformers import TrainingArguments

from ray import train
from ray.train.huggingface.transformers import RayTrainReportCallback, prepare_trainer
from ray.train.torch import TorchTrainer


def train_func(config):
    ...

    # Configure logging, saving, evaluation strategies as usual.
    args = TrainingArguments(
        ...,
        eval_strategy="epoch",
        save_strategy="epoch",
        logging_strategy="step",
    )

    trainer = transformers.Trainer(args, ...)

    # Add a report callback to transformers Trainer
    # =============================================
    trainer.add_callback(RayTrainReportCallback())
    trainer = prepare_trainer(trainer)

    trainer.train()


ray_trainer = TorchTrainer(
    train_func,
    run_config=train.RunConfig(
        checkpoint_config=train.CheckpointConfig(
            num_to_keep=3,
            checkpoint_score_attribute="eval_loss",  # The monitoring metric
            checkpoint_score_order="min",
        )
    ),
)
RayTrainReportCallback binds the latest metrics and checkpoints together. Configure logging_strategy, save_strategy, and evaluation_strategy so that the monitoring metric is logged at the same step as the checkpoint save.
For example, evaluation metrics such as eval_loss are logged during evaluation. To keep the best three checkpoints according to eval_loss, align the saving and evaluation frequency. The following are two examples of valid configurations:
args = TrainingArguments(
    ...,
    evaluation_strategy="epoch",
    save_strategy="epoch",
)

args = TrainingArguments(
    ...,
    evaluation_strategy="steps",
    save_strategy="steps",
    eval_steps=50,
    save_steps=100,
)

# And more ...
Option 2: Implement a custom report callback
If the default RayTrainReportCallback doesn’t fit your use case, implement your own callback. The following example collects the latest metrics and reports whenever the Trainer saves a checkpoint.
from ray import train

from transformers.trainer_callback import TrainerCallback


class MyTrainReportCallback(TrainerCallback):
    def __init__(self):
        super().__init__()
        self.metrics = {}

    def on_log(self, args, state, control, model=None, logs=None, **kwargs):
        """Log is called on evaluation step and logging step."""
        self.metrics.update(logs)

    def on_save(self, args, state, control, **kwargs):
        """Event called after a checkpoint save."""

        checkpoint = None
        if train.get_context().get_world_rank() == 0:
            # Build a Ray Train Checkpoint from the latest checkpoint
            checkpoint_path = transformers.trainer.get_last_checkpoint(args.output_dir)
            checkpoint = Checkpoint.from_directory(checkpoint_path)

        # Report to Ray Train with up-to-date metrics
        ray.train.report(metrics=self.metrics, checkpoint=checkpoint)

        # Clear the metrics buffer
        self.metrics = {}
In your own Transformers Trainer callback, you can customize when to report, such as in on_save, on_epoch_end, or on_evaluate. You can also customize what to report, such as custom metrics and checkpoint files.
Save checkpoints from multiple workers#
With model-parallel training strategies in which each worker has only a shard of the full model, you can save and report checkpoint shards from each worker in parallel.
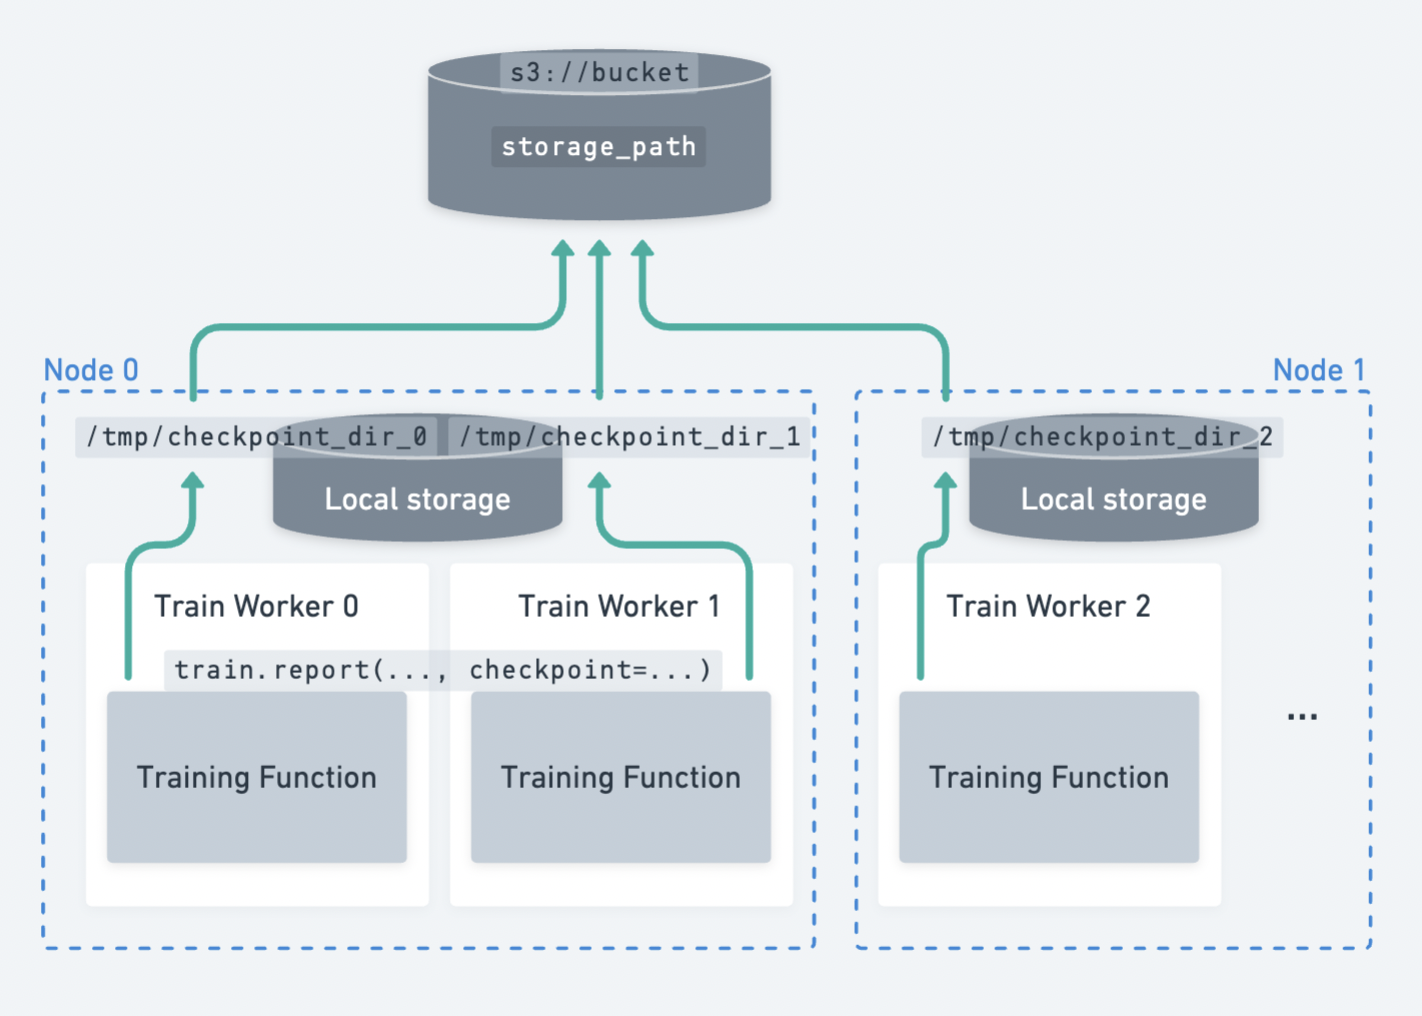
Distributed checkpointing in Ray Train. Each worker uploads its own checkpoint shard to persistent storage independently.#
Use distributed checkpointing to save checkpoints during model-parallel training, such as with DeepSpeed, FSDP, or Megatron-LM.
Distributed checkpointing is faster, which means less idle time and makes more frequent checkpointing practical. Each worker can upload its checkpoint shard in parallel, maximizing the network bandwidth of the cluster. Instead of a single node uploading the full model of size M, the cluster distributes the load across N nodes, each uploading a shard of size M / N.
Distributed checkpointing also avoids gathering the full model into a single worker’s CPU memory. That gather operation puts a large CPU memory requirement on the worker that performs checkpointing, and it’s a common source of out-of-memory (OOM) errors.
The following example shows distributed checkpointing with PyTorch:
from ray import train
from ray.train import Checkpoint
from ray.train.torch import TorchTrainer


def train_func(config):
    ...

    with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
        rank = train.get_context().get_world_rank()
        torch.save(
            ...,
            os.path.join(temp_checkpoint_dir, f"model-rank={rank}.pt"),
        )
        checkpoint = Checkpoint.from_directory(temp_checkpoint_dir)

        train.report(metrics, checkpoint=checkpoint)


trainer = TorchTrainer(
    train_func,
    scaling_config=train.ScalingConfig(num_workers=2),
    run_config=train.RunConfig(storage_path="s3://bucket/"),
)
# The checkpoint in cloud storage will contain: model-rank=0.pt, model-rank=1.pt
Note
Checkpoint files with the same name collide between workers. To avoid collisions, add a rank-specific suffix to checkpoint files.
A filename collision doesn’t raise an error. Instead, the last uploaded version is the one that persists. This is fine if the file contents are the same across all workers.
Model shard saving utilities from frameworks such as DeepSpeed already create rank-specific filenames, so you usually don’t need to handle this yourself.
Checkpoint upload modes#
By default, when you call report(), Ray Train synchronously pushes your checkpoint from checkpoint.path on local disk to checkpoint_dir_name on your storage_path. This is equivalent to calling report() with CheckpointUploadMode set to ray.train.CheckpointUploadMode.SYNC.
def train_fn(config):
    ...
    metrics = {...}
    with tempfile.TemporaryDirectory() as tmpdir:
        ...  # Save checkpoint to tmpdir
        checkpoint = Checkpoint.from_directory(tmpdir)
        train.report(
            metrics,
            checkpoint=checkpoint,
            checkpoint_upload_mode=train.CheckpointUploadMode.SYNC,
        )
Asynchronous checkpoint uploading#
To start the next training step while the checkpoint uploads, use ray.train.CheckpointUploadMode.ASYNC, which starts a new thread to upload the checkpoint. Asynchronous uploading helps with larger checkpoints that might take longer to upload. If you want to immediately upload only a small checkpoint, it might add unnecessary complexity, as the following paragraphs describe.
Each report call blocks until the previous call’s checkpoint upload completes, then starts a new checkpoint upload thread. Ray Train does this to avoid accumulating too many upload threads and potentially running out of memory.
Because report returns before the checkpoint upload completes, keep the local checkpoint directory alive until the upload finishes. Don’t write the checkpoint to a tempfile.TemporaryDirectory, because Python deletes that directory when its with block exits, which can happen before the upload finishes. A tempfile.TemporaryDirectory works with ray.train.CheckpointUploadMode.SYNC, because report returns only after the upload completes. The following example uses tempfile.mkdtemp instead. report also has a delete_local_checkpoint_after_upload parameter, which defaults to True with ray.train.CheckpointUploadMode.ASYNC, so Ray Train deletes the local checkpoint directory after the upload completes.
def train_fn(config):
    ...
    metrics = {...}
    tmpdir = tempfile.mkdtemp()
    ...  # Save checkpoint to tmpdir
    checkpoint = Checkpoint.from_directory(tmpdir)
    train.report(
        metrics,
        checkpoint=checkpoint,
        checkpoint_upload_mode=train.CheckpointUploadMode.ASYNC,
    )
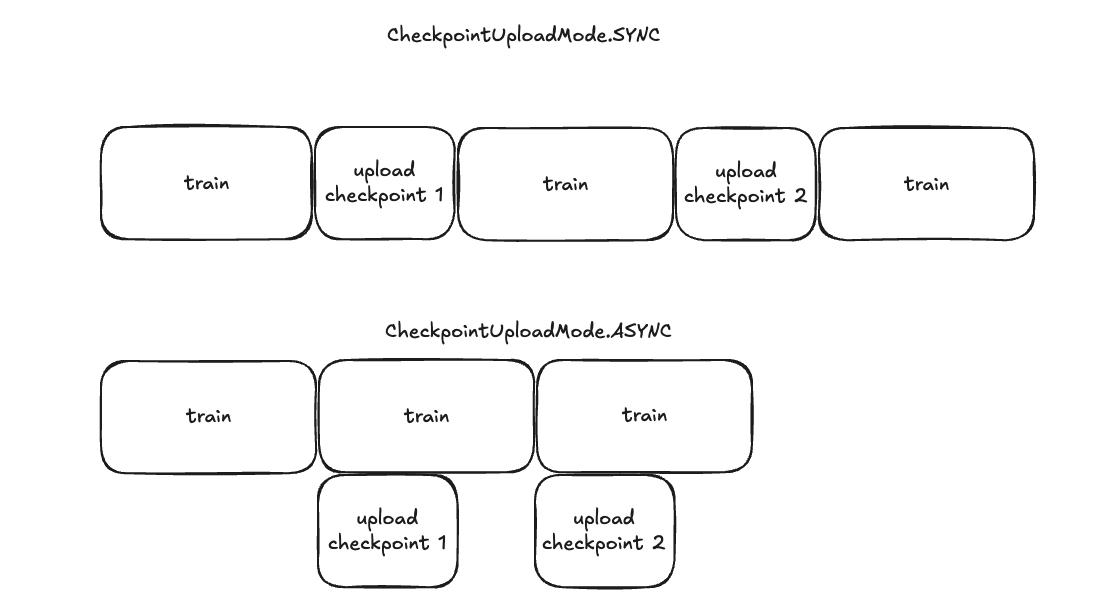
The difference between synchronous and asynchronous checkpoint uploading.#
Custom checkpoint uploading#
By default, report() uploads the checkpoint from disk to the remote storage_path with the PyArrow filesystem copying utilities, then reports the checkpoint to Ray Train. To upload the checkpoint yourself or with a third-party library such as Torch Distributed Checkpointing, use one of the following options:
To upload the checkpoint synchronously, first upload it to the storage_path, then report a reference to the uploaded checkpoint with ray.train.CheckpointUploadMode.NO_UPLOAD.
from s3torchconnector.dcp import S3StorageWriter
from torch.distributed.checkpoint.state_dict_saver import save
from torch.distributed.checkpoint.state_dict import get_state_dict


def train_fn(config):
    ...
    for epoch in range(config["num_epochs"]):
        # Directly upload checkpoint to s3 with Torch
        model, optimizer = ...
        storage_context = ray.train.get_context().get_storage()
        checkpoint_path = (
            f"s3://{storage_context.build_checkpoint_path_from_name(str(epoch))}"
        )
        storage_writer = S3StorageWriter(region="us-west-2", path=checkpoint_path)
        model_dict, opt_dict = get_state_dict(model=model, optimizers=optimizer)
        save(
            {"model": model_dict, "opt": opt_dict},
            storage_writer=storage_writer,
        )

        # Report that checkpoint to Ray Train
        metrics = {...}
        checkpoint = Checkpoint(checkpoint_path)
        train.report(
            metrics,
            checkpoint=checkpoint,
            checkpoint_upload_mode=train.CheckpointUploadMode.NO_UPLOAD,
        )
To upload the checkpoint asynchronously, set checkpoint_upload_mode to ray.train.CheckpointUploadMode.ASYNC and pass a checkpoint_upload_fn to ray.train.report. This function takes the Checkpoint and checkpoint_dir_name that you pass to ray.train.report and returns the persisted Checkpoint.
from torch.distributed.checkpoint.state_dict_saver import async_save
from s3torchconnector.dcp import S3StorageWriter
from torch.distributed.checkpoint.state_dict import get_state_dict

from ray import train
from ray.train import Checkpoint


def train_fn(config):
    ...
    for epoch in config["num_epochs"]:
        # Start async checkpoint upload to s3 with Torch
        model, optimizer = ...
        storage_context = train.get_context().get_storage()
        checkpoint_path = (
            f"s3://{storage_context.build_checkpoint_path_from_name(str(epoch))}"
        )
        storage_writer = S3StorageWriter(region="us-west-2", path=checkpoint_path)
        model_dict, opt_dict = get_state_dict(model=model, optimizers=optimizer)
        ckpt_ref = async_save(
            {"model": model_dict, "opt": opt_dict},
            storage_writer=storage_writer,
        )

        def wait_async_save(checkpoint, checkpoint_dir_name):
            # This function waits for checkpoint to be finalized before returning it as is
            ckpt_ref.result()
            return checkpoint

        # Ray Train kicks off a thread that waits for the async checkpoint upload to complete
        # before reporting the checkpoint
        metrics = {...}
        checkpoint = Checkpoint(checkpoint_path)
        train.report(
            metrics=metrics,
            checkpoint=checkpoint,
            checkpoint_upload_mode=train.CheckpointUploadMode.ASYNC,
            checkpoint_upload_fn=wait_async_save,
            # As uploading into the experiment directory then don't delete the checkpoint after upload is complete
            delete_local_checkpoint_after_upload=False,
        )

trainer = TorchTrainer(
   train_fn,
   train_loop_config={"num_epochs": 3},
   scaling_config=train.ScalingConfig(num_workers=2, use_gpu=True),
   # we need a cpu backend for async_save and a gpu backend for training
   torch_config=train.torch.TorchConfig(backend="cpu:gloo,cuda:nccl"),
   run_config=train.RunConfig(storage_path="s3://bucket/")
)
Warning
Don’t call ray.train.report in your checkpoint_upload_fn, because it may lead to unexpected behavior. Also avoid collective operations, such as report() or model.state_dict(), which can cause deadlocks. Return a checkpoint object from the upload function only after all checkpoint data is saved.
Note
Don’t pass a checkpoint_upload_fn with checkpoint_upload_mode=ray.train.CheckpointUploadMode.NO_UPLOAD, because Ray Train ignores checkpoint_upload_fn in that mode. You can pass a checkpoint_upload_fn with checkpoint_upload_mode=ray.train.CheckpointUploadMode.SYNC, but that’s equivalent to uploading the checkpoint yourself and reporting the checkpoint with ray.train.CheckpointUploadMode.NO_UPLOAD.
Configure checkpointing#
Configure checkpointing with CheckpointConfig. The primary option keeps only the top K checkpoints with respect to a metric, and Ray Train deletes lower-performing checkpoints to save storage space. By default, Ray Train keeps all checkpoints.
from ray.train import RunConfig, CheckpointConfig

# Example 1: Only keep the 2 *most recent* checkpoints and delete the others.
run_config = RunConfig(checkpoint_config=CheckpointConfig(num_to_keep=2))


# Example 2: Only keep the 2 *best* checkpoints and delete the others.
run_config = RunConfig(
    checkpoint_config=CheckpointConfig(
        num_to_keep=2,
        # *Best* checkpoints are determined by these params:
        checkpoint_score_attribute="mean_accuracy",
        checkpoint_score_order="max",
    ),
    # This will store checkpoints on S3.
    storage_path="s3://remote-bucket/location",
)
Note
To save the top num_to_keep checkpoints with respect to a metric through CheckpointConfig, always report the metric together with the checkpoints.
Use checkpoints during training#
During training, you might want to access the checkpoints you’ve reported, and their associated metrics, from the training workers. For example, you might report the best checkpoint so far to an experiment tracker. To do this, call get_all_reported_checkpoints() from your training function. It returns a list of ReportedCheckpoint objects. These represent all the Checkpoints and associated metrics that you’ve reported so far and that the checkpoint configuration has kept.
This function supports two consistency modes:
CheckpointConsistencyMode.COMMITTED: Block until the checkpoint from the latestray.train.reporthas been uploaded to persistent storage and committed.CheckpointConsistencyMode.VALIDATED: Block until the checkpoint from the latestray.train.reporthas been uploaded to persistent storage, committed, and validated. See Validate checkpoints asynchronously. This is the default consistency mode. It behaves the same asCheckpointConsistencyMode.COMMITTEDif your report didn’t start validation.
import ray.train
from ray.train import CheckpointConsistencyMode

def train_fn():
    for epoch in range(2):
        metrics = {"train/loss": 0.1}
        checkpoint = ...
        ray.train.report(
            metrics,
            checkpoint=checkpoint,
            validation=...,
        )

    # Get committed checkpoints which may still have ongoing validations.
    committed_checkpoints = ray.train.get_all_reported_checkpoints(
        consistency_mode=CheckpointConsistencyMode.COMMITTED)

    # Wait for all pending validations to finish to access reported checkpoints
    # with validation metrics attached.
    validated_checkpoints = ray.train.get_all_reported_checkpoints()
    ...
Use checkpoints after training#
Access the latest saved checkpoint with Result.checkpoint.
Access the full list of persisted checkpoints with Result.best_checkpoints. If you set CheckpointConfig(num_to_keep), this list contains the best num_to_keep checkpoints.
For a full guide on inspecting training results, see Inspect training results.
Checkpoint.as_directory and Checkpoint.to_directory are the two main APIs for interacting with Ray Train checkpoints:
from pathlib import Path

from ray.train import Checkpoint

# For demonstration, create a locally available directory with a `model.pt` file.
example_checkpoint_dir = Path("/tmp/test-checkpoint")
example_checkpoint_dir.mkdir(exist_ok=True)
example_checkpoint_dir.joinpath("model.pt").touch()

# Create the checkpoint, which is a reference to the directory.
checkpoint = Checkpoint.from_directory(example_checkpoint_dir)

# Inspect the checkpoint's contents with either `as_directory` or `to_directory`:
with checkpoint.as_directory() as checkpoint_dir:
    assert Path(checkpoint_dir).joinpath("model.pt").exists()

checkpoint_dir = checkpoint.to_directory()
assert Path(checkpoint_dir).joinpath("model.pt").exists()
For Lightning and Transformers, if you use the default RayTrainReportCallback to save checkpoints in your training function, retrieve the original checkpoint files as follows:
# After training finished
checkpoint = result.checkpoint
with checkpoint.as_directory() as checkpoint_dir:
    lightning_checkpoint_path = f"{checkpoint_dir}/checkpoint.ckpt"
# After training finished
checkpoint = result.checkpoint
with checkpoint.as_directory() as checkpoint_dir:
    hf_checkpoint_path = f"{checkpoint_dir}/checkpoint/"
Restore training state from a checkpoint#
To enable fault tolerance, modify your training loop to restore training state from a Checkpoint.
In the training function, access the Checkpoint to restore from with ray.train.get_checkpoint.
During automatic failure recovery, ray.train.get_checkpoint returns the latest reported checkpoint.
For details on restoration and fault tolerance, see Handle failures and node preemption.
import os
import tempfile

import numpy as np
import torch
import torch.nn as nn
from torch.optim import Adam

import ray.train.torch
from ray import train
from ray.train import Checkpoint, ScalingConfig
from ray.train.torch import TorchTrainer


def train_func(config):
    n = 100
    # create a toy dataset
    # data   : X - dim = (n, 4)
    # target : Y - dim = (n, 1)
    X = torch.Tensor(np.random.normal(0, 1, size=(n, 4)))
    Y = torch.Tensor(np.random.uniform(0, 1, size=(n, 1)))
    # toy neural network : 1-layer
    model = nn.Linear(4, 1)
    optimizer = Adam(model.parameters(), lr=3e-4)
    criterion = nn.MSELoss()

    # Wrap the model in DDP and move it to GPU.
    model = ray.train.torch.prepare_model(model)

    # ====== Resume training state from the checkpoint. ======
    start_epoch = 0
    checkpoint = train.get_checkpoint()
    if checkpoint:
        with checkpoint.as_directory() as checkpoint_dir:
            model_state_dict = torch.load(
                os.path.join(checkpoint_dir, "model.pt"),
                # map_location=...,  # Load onto a different device if needed.
            )
            model.module.load_state_dict(model_state_dict)
            optimizer.load_state_dict(
                torch.load(os.path.join(checkpoint_dir, "optimizer.pt"))
            )
            start_epoch = (
                torch.load(os.path.join(checkpoint_dir, "extra_state.pt"))["epoch"] + 1
            )
    # ========================================================

    for epoch in range(start_epoch, config["num_epochs"]):
        y = model.forward(X)
        loss = criterion(y, Y)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()

        metrics = {"loss": loss.item()}

        with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
            checkpoint = None

            should_checkpoint = epoch % config.get("checkpoint_freq", 1) == 0
            # In standard DDP training, where the model is the same across all ranks,
            # only the global rank 0 worker needs to save and report the checkpoint
            if train.get_context().get_world_rank() == 0 and should_checkpoint:
                # === Make sure to save all state needed for resuming training ===
                torch.save(
                    model.module.state_dict(),  # NOTE: Unwrap the model.
                    os.path.join(temp_checkpoint_dir, "model.pt"),
                )
                torch.save(
                    optimizer.state_dict(),
                    os.path.join(temp_checkpoint_dir, "optimizer.pt"),
                )
                torch.save(
                    {"epoch": epoch},
                    os.path.join(temp_checkpoint_dir, "extra_state.pt"),
                )
                # ================================================================
                checkpoint = Checkpoint.from_directory(temp_checkpoint_dir)

            train.report(metrics, checkpoint=checkpoint)

        if epoch == 1:
            raise RuntimeError("Intentional error to showcase restoration!")


trainer = TorchTrainer(
    train_func,
    train_loop_config={"num_epochs": 5},
    scaling_config=ScalingConfig(num_workers=2),
    run_config=train.RunConfig(failure_config=train.FailureConfig(max_failures=1)),
)
result = trainer.fit()
import os

from ray import train
from ray.train import Checkpoint
from ray.train.torch import TorchTrainer
from ray.train.lightning import RayTrainReportCallback


def train_func():
    model = MyLightningModule(...)
    datamodule = MyLightningDataModule(...)
    trainer = pl.Trainer(..., callbacks=[RayTrainReportCallback()])

    checkpoint = train.get_checkpoint()
    if checkpoint:
        with checkpoint.as_directory() as ckpt_dir:
            ckpt_path = os.path.join(ckpt_dir, RayTrainReportCallback.CHECKPOINT_NAME)
            trainer.fit(model, datamodule=datamodule, ckpt_path=ckpt_path)
    else:
        trainer.fit(model, datamodule=datamodule)


ray_trainer = TorchTrainer(
    train_func,
    scaling_config=train.ScalingConfig(num_workers=2),
    run_config=train.RunConfig(
        checkpoint_config=train.CheckpointConfig(num_to_keep=2),
    ),
)
Note
These examples use Checkpoint.as_directory to view the checkpoint contents as a local directory.
If the checkpoint points to a local directory, this method returns the local directory path without making a copy.
If the checkpoint points to a remote directory, this method downloads the checkpoint to a local temporary directory and returns the path to that directory.
If multiple processes on the same node call this method simultaneously, only one process performs the download, and the others wait for it to finish. After the download finishes, all processes receive the same local temporary directory to read from.
After all processes finish working with the checkpoint, the temporary directory is cleaned up.