Handle failures and node preemption#
Important
This guide covers fault tolerance for Ray Train V2, which is the default starting in Ray 2.51. In Ray 2.43 through 2.50, enable Ray Train V2 by setting the environment variable RAY_TRAIN_V2_ENABLED=1.
For information about the deprecation and migration, see Fault tolerance API deprecations.
Ray Train provides fault tolerance at three levels:
Worker process fault tolerance: Handles errors in one or more workers while they run the training function.
Worker node fault tolerance: Handles node failures during training.
Job driver fault tolerance: Handles a crash of the Ray Train driver process, after which training needs to start again, possibly on a new cluster.
This guide shows how to configure and use these fault tolerance mechanisms. It also shows how to save a just-in-time checkpoint before a node is preempted, so that a restart loses as little progress as possible.
Worker process and node fault tolerance#
Worker process failures are errors that occur within the training function of a worker, such as GPU out-of-memory (OOM) errors, cloud storage access errors, or other runtime errors.
Node failures are errors that bring down the entire node, including node preemption, OOM, network partitions, or other hardware failures. This section covers worker node failures. Job driver fault tolerance covers recovery from head node failures.
You can configure Ray Train to recover automatically from worker process and worker node failures. When Ray Train detects a failure, it shuts down all the workers. New nodes join the cluster if necessary, and Ray Train starts a new set of workers. The restarted workers can resume training by loading the latest checkpoint.
To retain progress after recovery, implement logic in your training function for both saving and loading checkpoints. Otherwise, training starts from scratch.
Each recovery from a worker process or node failure counts as a retry. To configure the number of retries, set the max_failures attribute of the FailureConfig in the RunConfig that you pass to the trainer. The default, max_failures=0, disables worker fault tolerance.
import ray.train

# Tries to recover a run up to this many times.
failure_config = ray.train.FailureConfig(max_failures=2)

# No limit on the number of retries.
failure_config = ray.train.FailureConfig(max_failures=-1)
The following example shows a complete PyTorch training script with worker fault tolerance:
import tempfile
import uuid

import ray.train
import ray.train.torch


def train_fn_per_worker(train_loop_config: dict):
    # [1] Train worker restoration logic.
    checkpoint = ray.train.get_checkpoint()
    if checkpoint:
        with checkpoint.as_directory() as temp_checkpoint_dir:
            # model.load_state_dict(torch.load(...))
            ...

    # [2] Checkpoint saving and reporting logic.
    with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
        # torch.save(...)
        ray.train.report(
            {"loss": 0.1},
            checkpoint=ray.train.Checkpoint.from_directory(temp_checkpoint_dir),
        )


trainer = ray.train.torch.TorchTrainer(
    train_fn_per_worker,
    scaling_config=ray.train.ScalingConfig(num_workers=4),
    run_config=ray.train.RunConfig(
        # (If multi-node, configure S3 / NFS as the storage path.)
        # storage_path="s3://...",
        name=f"train_run-{uuid.uuid4().hex}",
        # [3] Enable worker-level fault tolerance to gracefully handle
        # Train worker failures.
        failure_config=ray.train.FailureConfig(max_failures=3),
    ),
)
trainer.fit()
Which checkpoint is restored?#
Ray Train populates ray.train.get_checkpoint() with the latest available checkpoint reported to Ray Train. The Checkpoint object that this method returns has the as_directory() and to_directory() methods, which download the checkpoint from the RunConfig(storage_path) to local disk.
Note
as_directory() and to_directory() download the checkpoint only once per node, even if the node runs multiple workers. The workers share the same checkpoint directory on local disk.
Illustrated example#
Consider a cluster with a CPU head node and two GPU worker nodes. Four GPU training workers run on the two worker nodes. You’ve configured the storage path to use cloud storage, which is where checkpoints are saved.
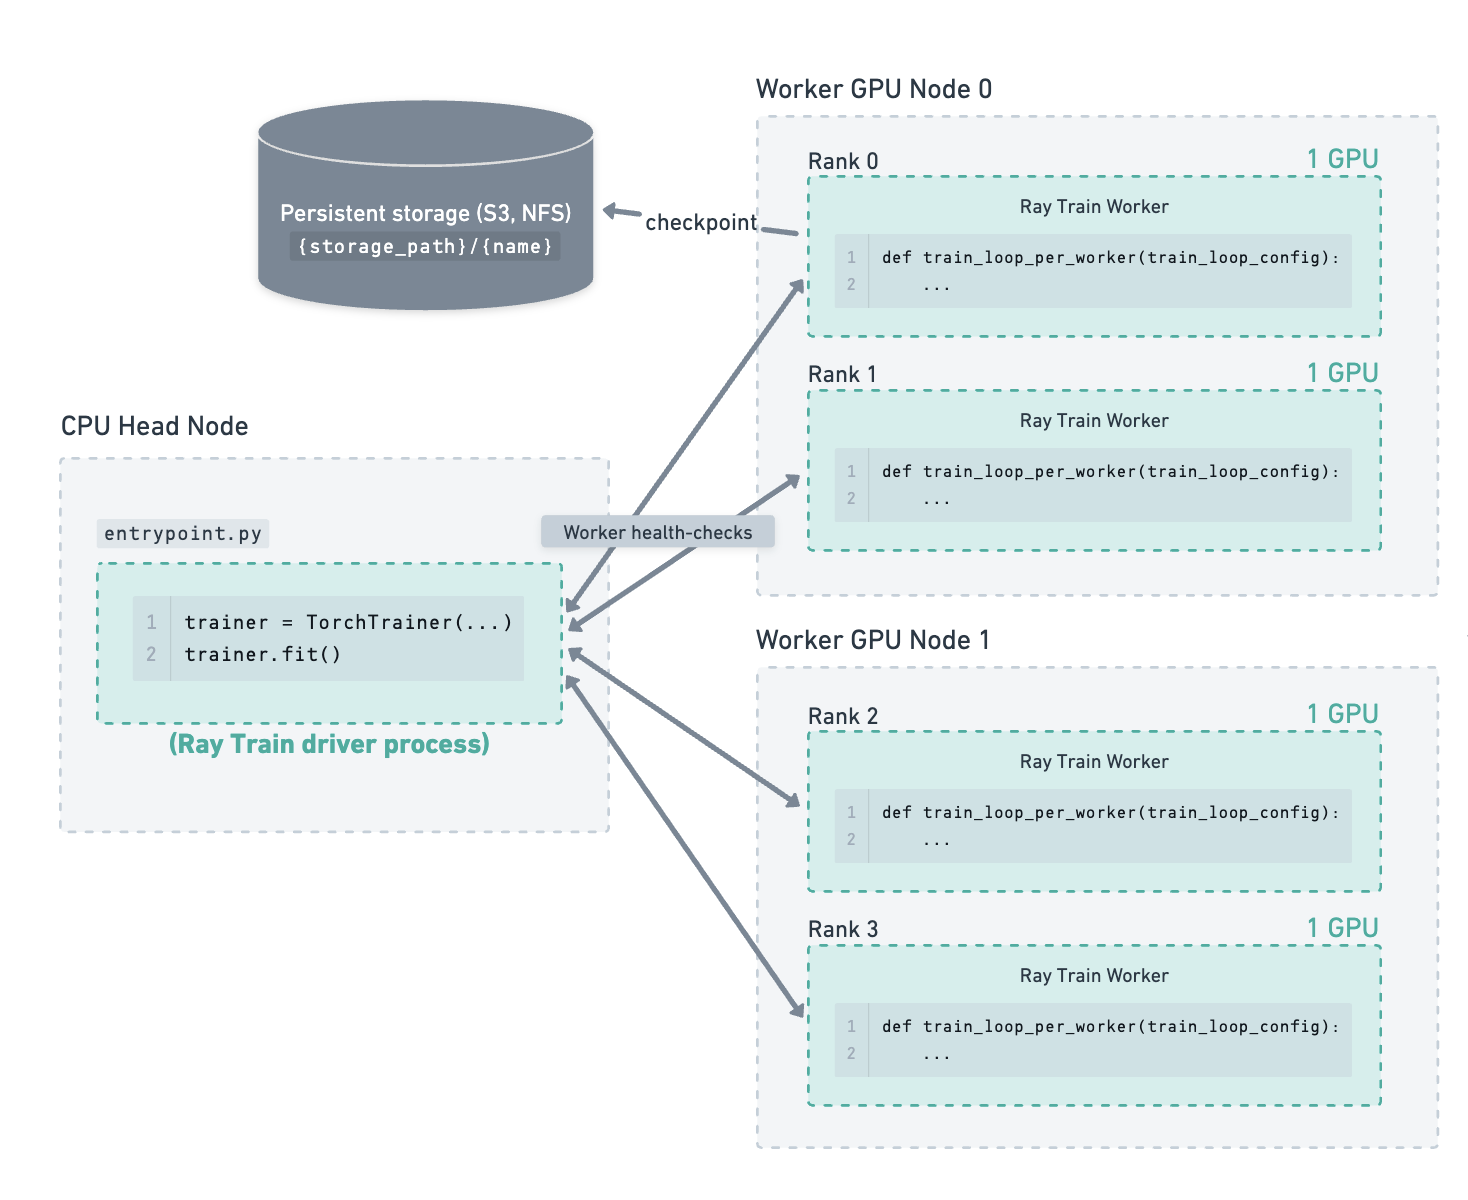
Training has been running for some time, and the latest checkpoint has been saved to cloud storage.#
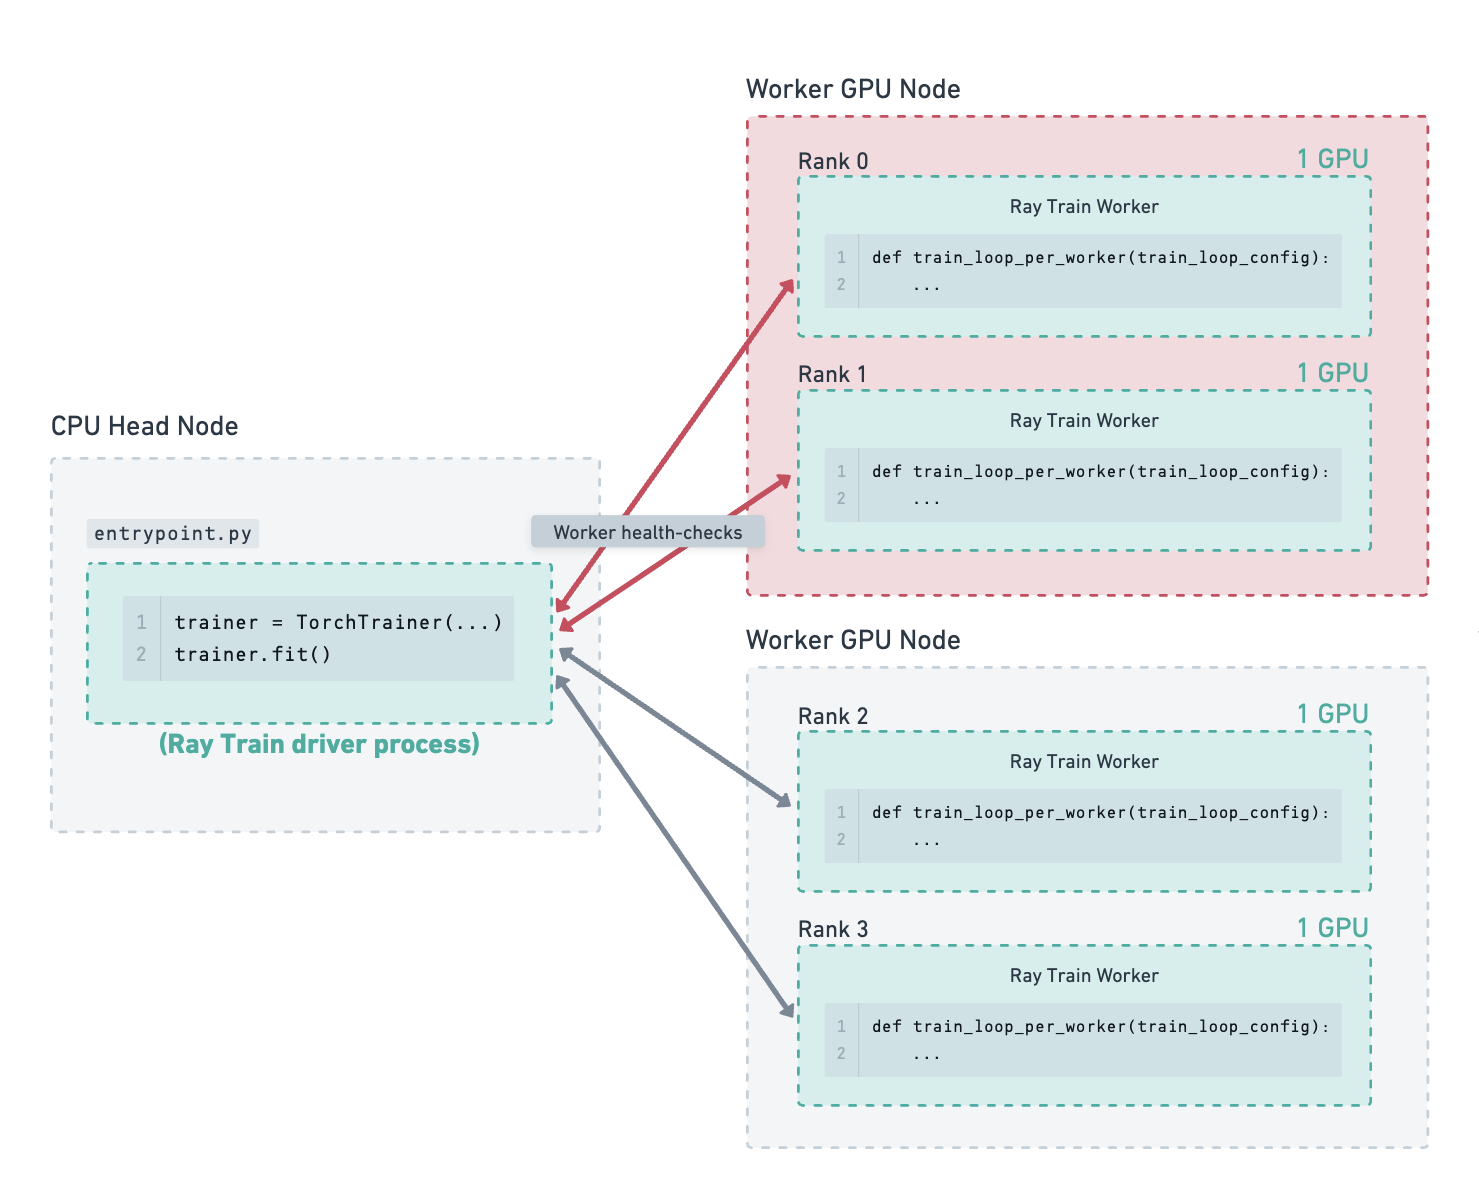
One of the GPU worker nodes fails because of a hardware fault. Ray Train detects this failure and shuts down all the workers.
Because the number of failures detected so far is less than the configured max_failures, Ray Train attempts to restart training
rather than exit and raise an error.#
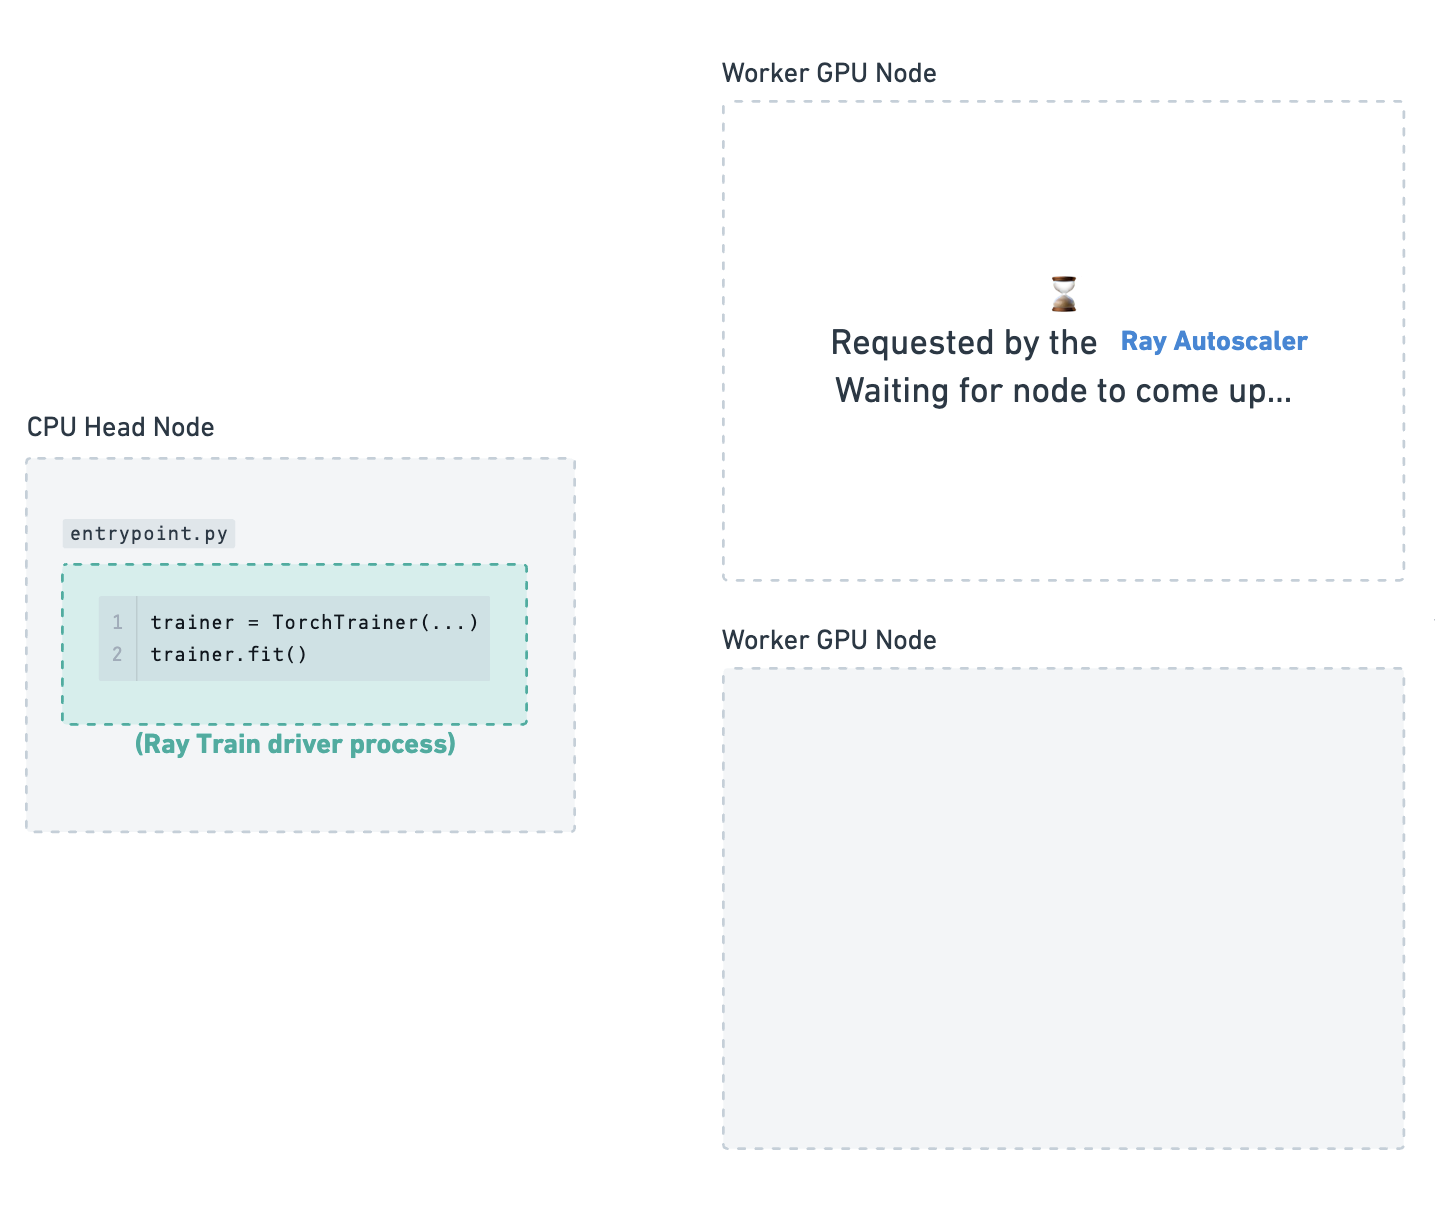
Ray Train requests a new worker node to join the cluster and waits for it to come up.#
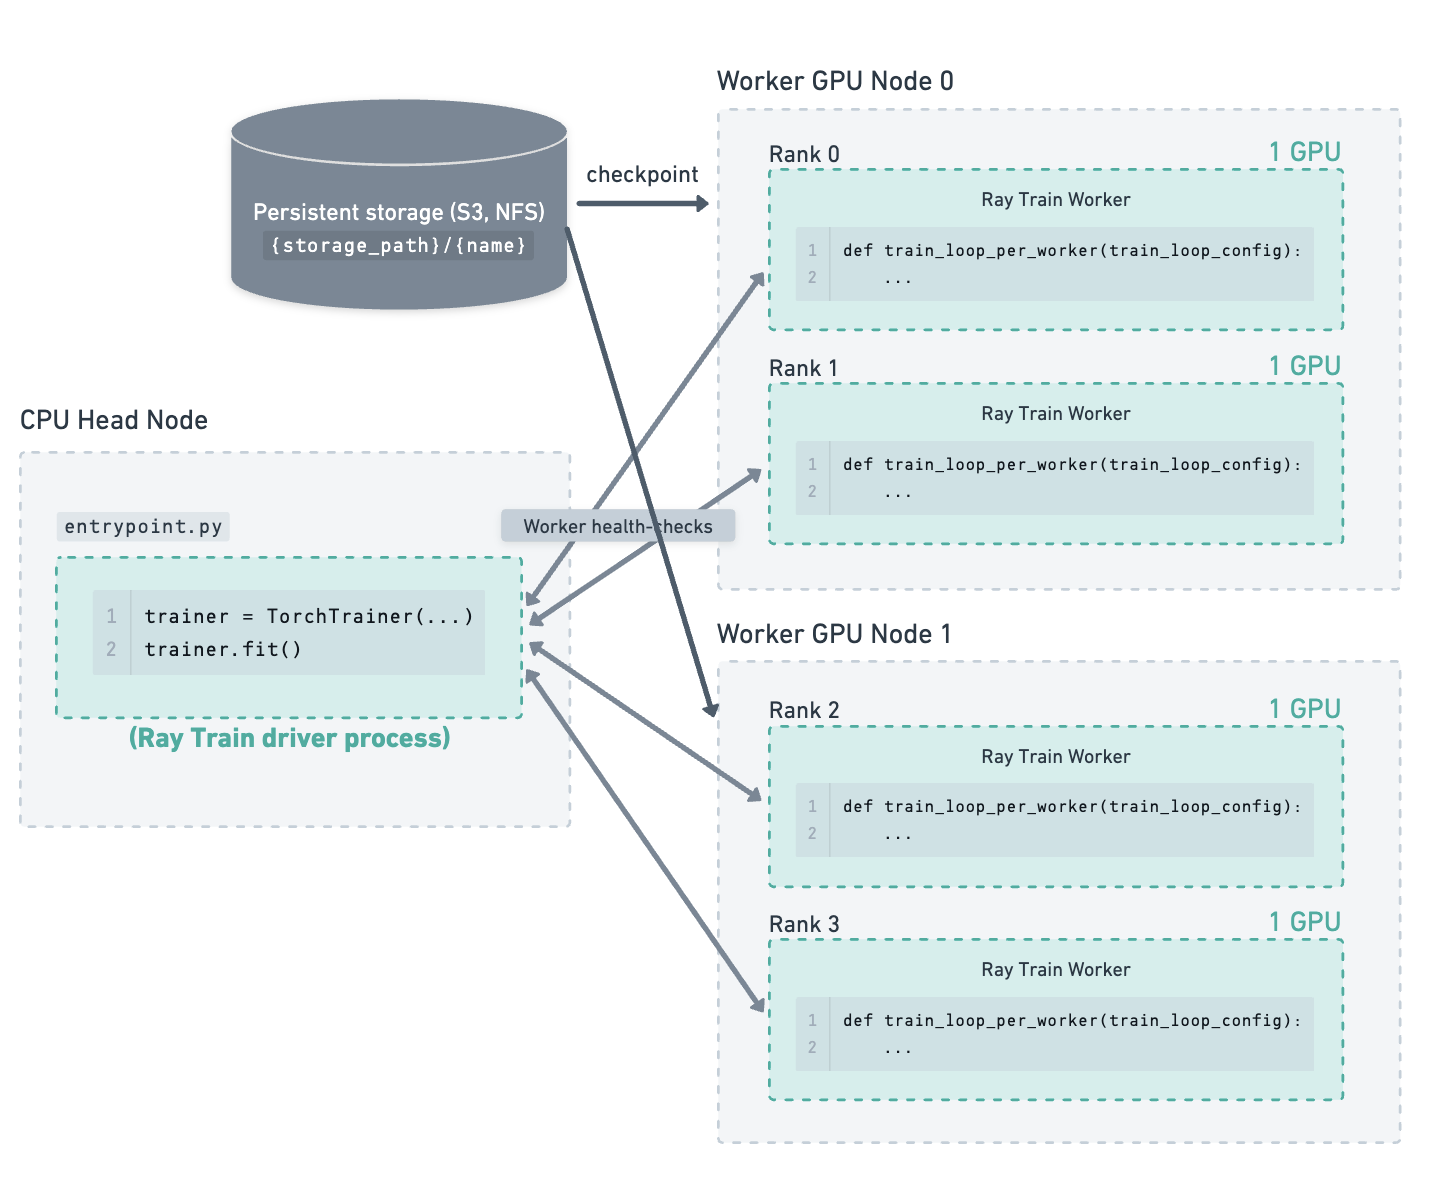
The new worker node has joined the cluster. Ray Train restarts all the worker processes and provides them with the latest checkpoint. The workers download the checkpoint from storage and use it to resume training.#
Just-in-time checkpointing on node preemption#
Cloud providers preempt spot instances and preemptible virtual machines with short notice. AWS gives about two minutes of notice before it preempts a spot instance, and GCP gives about 30 seconds. If your training run only checkpoints periodically, a preemption discards every step since the last checkpoint.
Ray Train can react to that notice. When Ray marks a node that hosts one of your workers as draining because of a preemption, ray.train.get_preemption_info() returns a PreemptionInfo. Your training function can then save a just-in-time checkpoint before the node is preempted, so the restarted run resumes from the step where the preemption happened.
To use just-in-time checkpointing, first make sure that your cluster sends preemption signals to Ray, then call get_preemption_info() in your training function.
Send preemption signals to Ray#
Ray Train only reacts to preemptions that Ray Core knows about. It reads the draining nodes and their deadlines from the Ray Global Control Service (GCS). Something outside Ray Train has to watch for the preemption notice from the cloud provider and mark the node as draining with the DRAIN_NODE_REASON_PREEMPTION reason. How you set this up depends on where you run Ray:
Managed Ray platforms such as Anyscale watch for preemption notices on every node and drain the node for you. You don’t need to configure anything.
KubeRay starts Ray in each Pod with ray start --block. When that process receives SIGTERM, it sends the drain request to the GCS itself, with the DRAIN_NODE_REASON_PREEMPTION reason, before it shuts down Ray. You don’t need to run a separate process to send it. Kubernetes sends SIGTERM when it deletes a Pod. Whether Kubernetes deletes the Pods on a preempted node depends on your cluster setup, such as graceful node shutdown on GKE or the AWS Node Termination Handler on Amazon EKS.
The drain deadline is RAY_GRACEFUL_SHUTDOWN_DRAIN_TIMEOUT_S seconds after SIGTERM, and the default is 30 seconds. To change it, set the environment variable on the Ray container. Set terminationGracePeriodSeconds on the Pod to a higher value than this timeout, so that Kubernetes doesn’t kill the Pod before the drain window ends.
The drain window starts at SIGTERM, not at the preemption notice from the cloud provider, so it’s limited by the Pod’s termination grace period. To start the drain as soon as the cloud provider sends the notice, run a watcher as described in the Self-managed clusters tab.
Run a process on each node that polls the preemption notice from the cloud provider, such as the spot instance action on AWS or the preempted flag on GCP. When the notice arrives, drain the node with ray drain-node --node-id <node-id> --reason DRAIN_NODE_REASON_PREEMPTION --reason-message <message> --deadline-remaining-seconds <seconds>.
The ray drain-node command is a developer API, and Ray’s public API stability guarantees don’t cover it.
Choose a drain deadline that’s shorter than the preemption notice. Ray Train restarts the run at the deadline, and it can only shut down the workers cleanly while the preempted node is still reachable. For example, with the two-minute AWS spot notice, a 60-second deadline leaves time for Ray Train to shut down the workers before AWS preempts the instance.
To test your just-in-time checkpointing on any cluster, drain a worker node manually with ray drain-node.
How does Ray Train handle a preemption?#
Ray Train handles a preemption in four steps:
Ray Train polls Ray Core every few seconds for draining nodes and ignores nodes that don’t host training workers. On a TPU slice, a drain on any host marks every worker in the slice as preempted, because the cloud provider preempts the whole slice at once.
Every worker, including workers on healthy nodes, receives the same
PreemptionInfofromget_preemption_info(). It lists the preempted node IDs, the affected world ranks inpreempted_ranks, and the drain deadline indeadline_ms, which is a UNIX timestamp in milliseconds.Ray Train keeps every worker running so that your code can save a checkpoint. It waits until all workers exit or the drain deadline passes. If the drain has no deadline, Ray Train waits 120 seconds after it detects the preemption.
Ray Train shuts down the worker group and restarts the run from the latest reported checkpoint on replacement nodes.
Each restart counts against FailureConfig(max_preemption_failures), a retry budget that’s separate from max_failures. The default value of -1 retries without a limit, so preemptions don’t use up the retries that you reserve for real failures such as out-of-memory errors. After the run exhausts the budget, trainer.fit() raises a PreemptionError.
Save a just-in-time checkpoint#
Call get_preemption_info() in your training loop. When it returns a PreemptionInfo, save and report one more checkpoint. The restarted run resumes from the just-in-time checkpoint:
import tempfile
import uuid

import ray.train
import ray.train.torch


def save_checkpoint(metrics: dict):
    with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
        checkpoint = None
        # Save the checkpoint from rank 0, which holds a full model replica.
        if ray.train.get_context().get_world_rank() == 0:
            # torch.save(...)
            checkpoint = ray.train.Checkpoint.from_directory(temp_checkpoint_dir)
        # Call `report` on every rank, with or without a checkpoint.
        ray.train.report(metrics, checkpoint=checkpoint)


def train_fn_per_worker(config: dict):
    start_step = 0

    # [1] Resume from the latest checkpoint, which can be a just-in-time one.
    checkpoint = ray.train.get_checkpoint()
    if checkpoint:
        with checkpoint.as_directory() as checkpoint_dir:
            # model.load_state_dict(torch.load(...))
            # start_step = ...
            ...

    saved_on_preemption = False
    for step in range(start_step, config["num_steps"]):
        ...  # Run a training step.

        # [2] Call `get_preemption_info` on every rank the same number of
        # times, because it synchronizes the answer across all workers.
        preemption_info = ray.train.get_preemption_info()
        if preemption_info is not None and not saved_on_preemption:
            # Save one extra checkpoint before the node is preempted. Keep
            # the loop running, because returning ends the run.
            save_checkpoint({"step": step})
            saved_on_preemption = True


trainer = ray.train.torch.TorchTrainer(
    train_fn_per_worker,
    train_loop_config={"num_steps": 10},
    scaling_config=ray.train.ScalingConfig(num_workers=2),
    run_config=ray.train.RunConfig(
        # (If multi-node, configure S3 / NFS as the storage path.)
        # storage_path="s3://...",
        name=f"train_run-{uuid.uuid4().hex}",
        failure_config=ray.train.FailureConfig(
            # [3] Retry preemptions from a budget that's separate from
            # `max_failures`. The default of -1 retries without a limit.
            max_preemption_failures=-1,
            max_failures=3,
        ),
    ),
)
trainer.fit()
Follow these rules when you call get_preemption_info():
Call it from every worker the same number of times. It acts as a barrier that broadcasts the rank 0 result to all workers, so every worker acts on the same answer. If one worker skips a call, the other workers hang.
Save the checkpoint once, then keep training. The return value stays set until the run restarts, so track whether you already saved, as
saved_on_preemptiondoes in the example.Fit the checkpoint upload into the drain window. Ray Train registers the checkpoint only after the upload to persistent storage completes. If the upload takes longer than the drain window, see Finish slow checkpoints without the preempted workers.
Warning
Don’t return from the training function after you save the just-in-time checkpoint. When the training function returns without an error, Ray Train marks the run as finished, even while a preemption is in progress.
Finish slow checkpoints without the preempted workers#
By default, ray.train.report() and get_preemption_info() wait for every worker. If the preempted node shuts down before its workers reach report, the surviving workers block until the drain deadline, and the just-in-time checkpoint is lost. Ray Train also shuts down the surviving workers as soon as the drain deadline passes, which can interrupt an upload.
To finish a checkpoint that takes longer than the drain window, set two FailureConfig options:
import ray.train

failure_config = ray.train.FailureConfig(
    max_preemption_failures=-1,
    # Complete `report` and `get_preemption_info` without the workers on
    # the preempted node.
    relax_collectives_on_preemption=True,
    # Keep the surviving workers running for up to two minutes past the
    # drain deadline, so that a slow checkpoint upload can finish.
    preemption_grace_s=120.0,
)
With relax_collectives_on_preemption=True, report() and get_preemption_info() complete with only the surviving workers, so the survivors can commit the checkpoint on their own. preemption_grace_s keeps the surviving workers running for that many seconds past the drain deadline, so the upload can finish before Ray Train restarts the run.
If a training step and a checkpoint upload fit inside the drain window, you don’t need either option. The preempted workers are still alive and take part in the checkpoint.
Warning
Only set relax_collectives_on_preemption=True if the surviving workers can write a complete checkpoint on their own. The option has three limitations:
Rank 0 must survive. Rank 0 sends the checkpoint directory name to the other workers, so if rank 0 is on a preempted node, Ray Train ignores the option and waits for every worker.
The checkpoint can’t depend on state that only the preempted workers hold. Data-parallel training where rank 0 saves a full model replica, as in the preceding example, works. If each worker saves its own shard, as with FSDP or DeepSpeed ZeRO, Ray Train can commit a checkpoint that’s missing the shards of the preempted workers.
Ray Train only relaxes two collectives:
report()andget_preemption_info(). Every other collective still waits for every worker and hangs after a preempted peer shuts down. This includesray.train.collective.barrier()andray.train.collective.broadcast_from_rank_zero(), as well as framework collectives in your code such astorch.distributed.barrier()or a gather of a sharded state dict.
Job driver fault tolerance#
Job driver fault tolerance handles cases where the Ray Train driver process is interrupted. The Ray Train driver process is the process that calls trainer.fit(), and it usually runs on the head node of the cluster.
Any of the following events can interrupt the driver process:
You interrupt the run manually, for example with Ctrl+C.
The head node, which runs the driver process, crashes. For example, it runs out of memory or out of disk.
The entire cluster goes down, for example because of a network error that affects all nodes.
In these cases, the Ray Train driver needs to be launched again. To pick up where the previous run left off, the relaunched driver needs to find a minimal amount of run state. This state includes the latest reported checkpoints, which are located at the storage path. Ray Train fetches the latest checkpoint information from storage and passes it to the newly launched worker processes to resume training.
To find this run state, Ray Train relies on you passing the same RunConfig(storage_path, name) pair as the previous run. If the storage_path or name doesn’t match, Ray Train can’t find the previous run state and starts a new run from scratch.
Warning
If you reuse a name unintentionally, Ray Train fetches the previous run state, even if you’re trying to start a new run. Always pass a unique run name when you launch a new run, so that name uniquely identifies a training job.
Note
Job driver crashes and interrupts don’t count toward the max_failures limit of worker fault tolerance.
The following example training script shows best practices for job driver fault tolerance:
# entrypoint.py

import argparse
import tempfile
import uuid

import ray.train
import ray.train.torch


def train_fn_per_worker(train_loop_config: dict):
    # [1] Train worker restoration logic.
    checkpoint = ray.train.get_checkpoint()
    if checkpoint:
        with checkpoint.as_directory() as temp_checkpoint_dir:
            # model.load_state_dict(torch.load(...))
            ...

    # [2] Checkpoint saving and reporting logic.
    with tempfile.TemporaryDirectory() as temp_checkpoint_dir:
        # torch.save(...)
        ray.train.report(
            {"loss": 0.1},
            checkpoint=ray.train.Checkpoint.from_directory(temp_checkpoint_dir),
        )


if __name__ == "__main__":
    parser = argparse.ArgumentParser()
    parser.add_argument("--storage_path", type=str, required=True)
    parser.add_argument("--run_name", type=str, required=True)
    args = parser.parse_args()

    trainer = ray.train.torch.TorchTrainer(
        train_fn_per_worker,
        scaling_config=ray.train.ScalingConfig(num_workers=4),
        run_config=ray.train.RunConfig(
            # [3] Enable worker-level fault tolerance to gracefully handle
            # Train worker failures.
            failure_config=ray.train.FailureConfig(max_failures=3),
            # [4] (Recommendation) The (storage_path, name) pair should be
            # determined by the job submitter and passed in as arguments
            # to the entrypoint script.
            storage_path=args.storage_path,
            name=args.run_name,
        ),
    )
    trainer.fit()
Launch the entrypoint script with the following command:
python entrypoint.py --storage_path s3://my_bucket/ --run_name unique_run_id=da823d5
If the job is interrupted, run the same command to resume training. This example uses da823d5 as the run ID, which you choose when you launch the job. You can often reuse this ID for other purposes, such as the wandb or mlflow run ID.
Illustrated example#
Consider a cluster with a CPU head node and two GPU worker nodes. Four GPU training workers run on the two worker nodes. You’ve configured the storage path to use cloud storage, which is where checkpoints are saved.
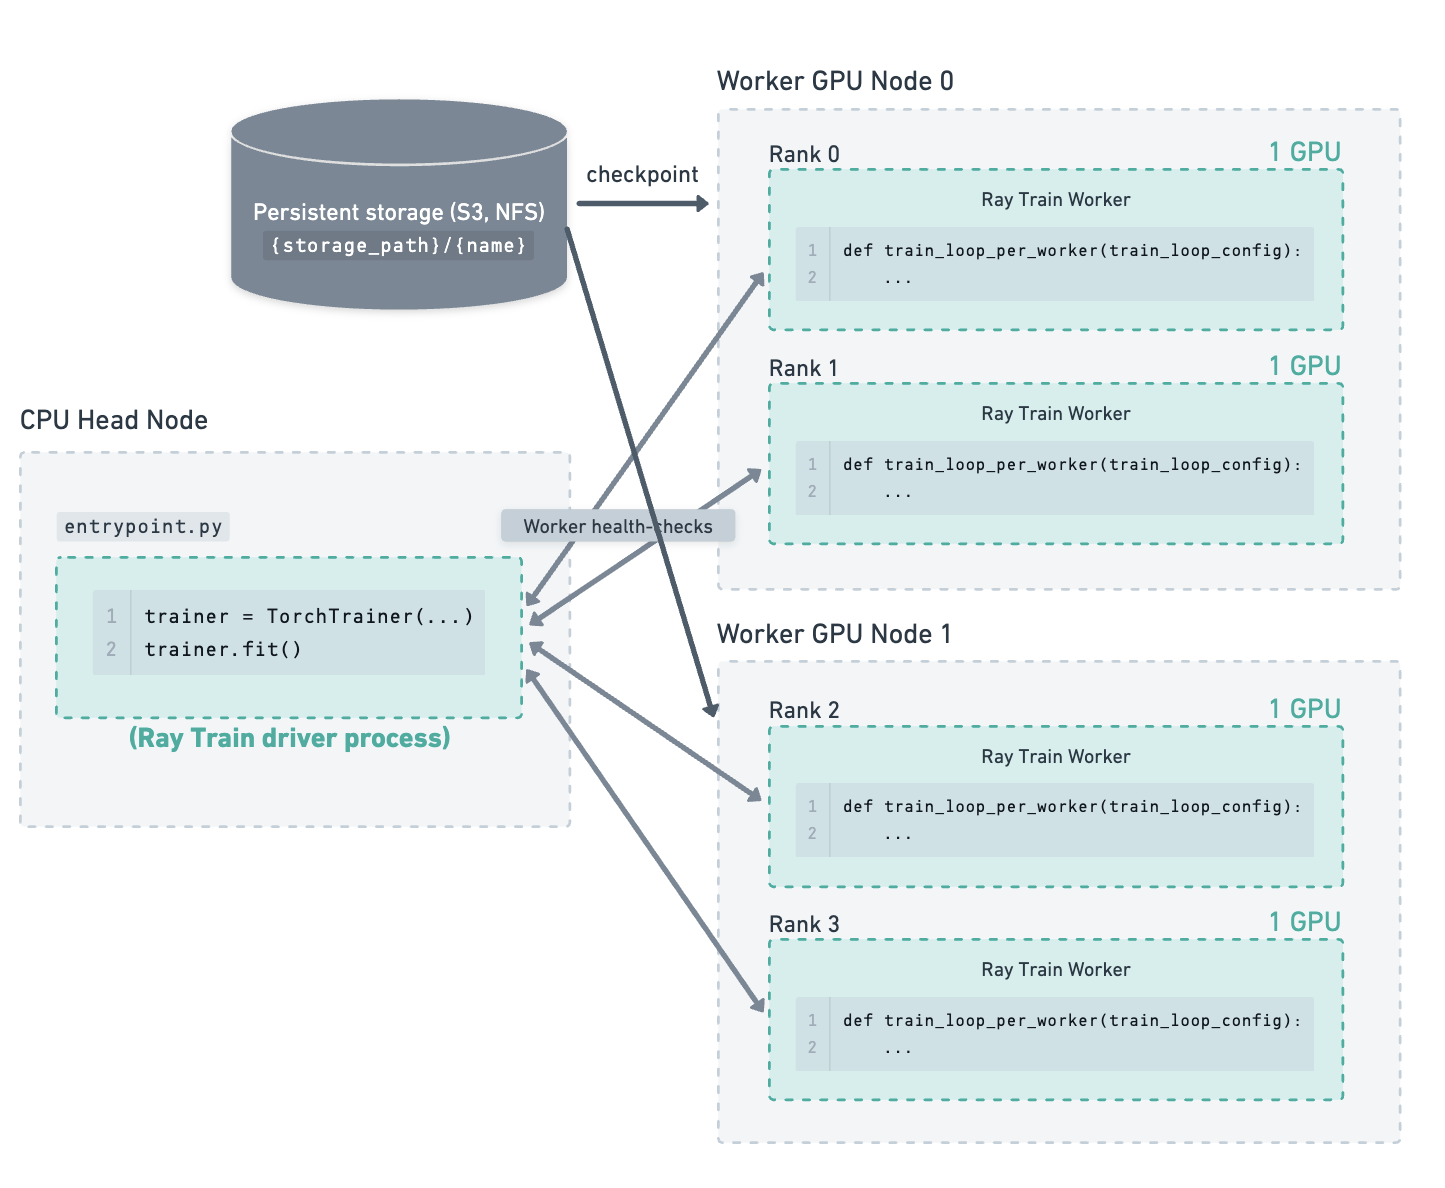
Training has been running for some time, and the latest checkpoints and run state have been saved to storage.#
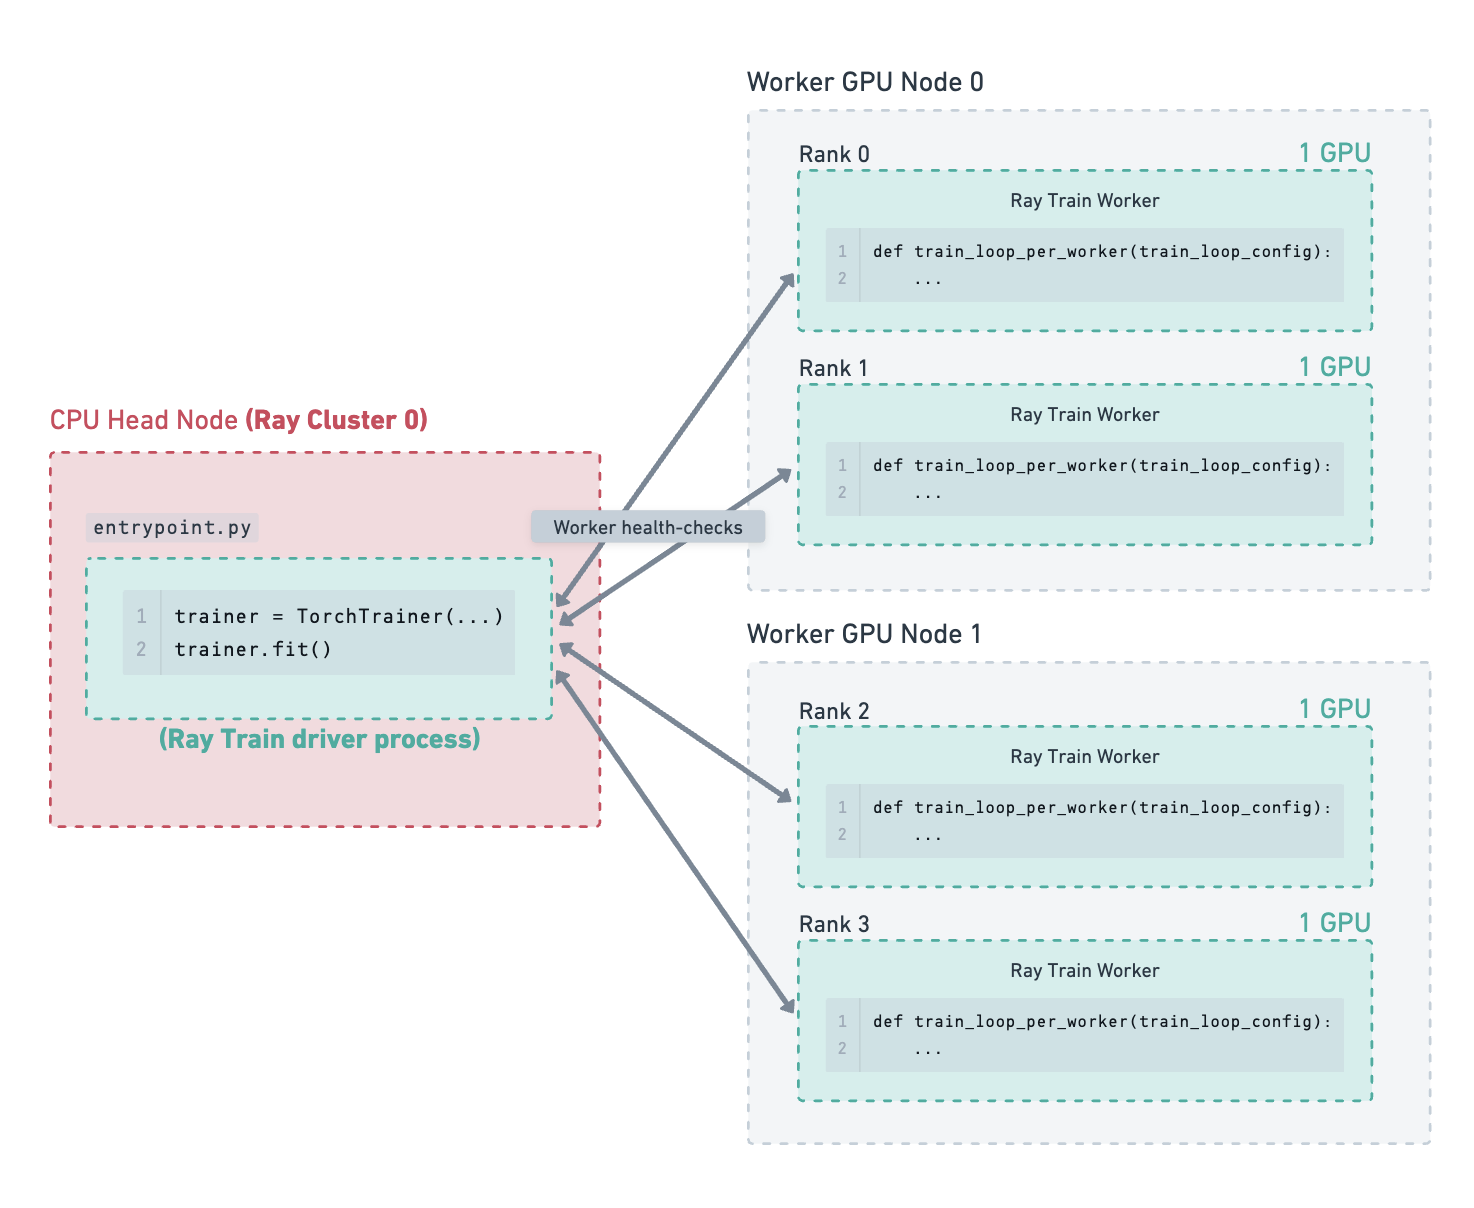
The head node crashes, for example because of an out-of-memory error, which interrupts the Ray Train driver process.#
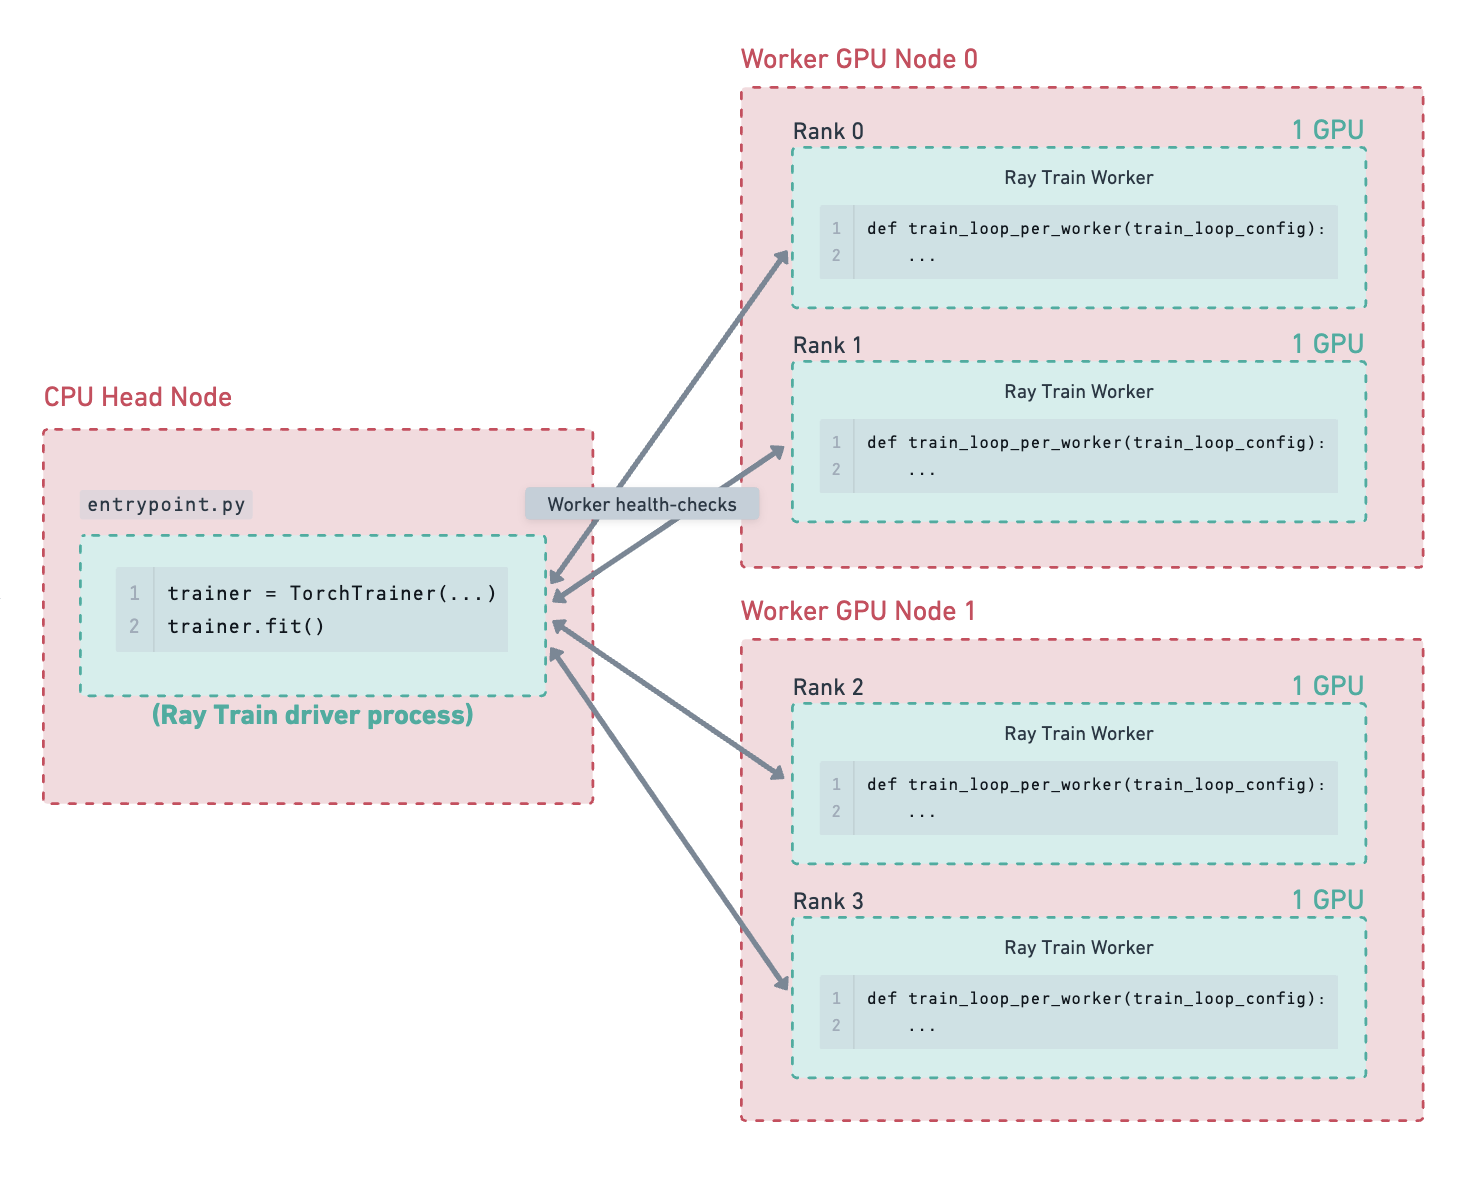
The head node failure brings down the entire cluster.#
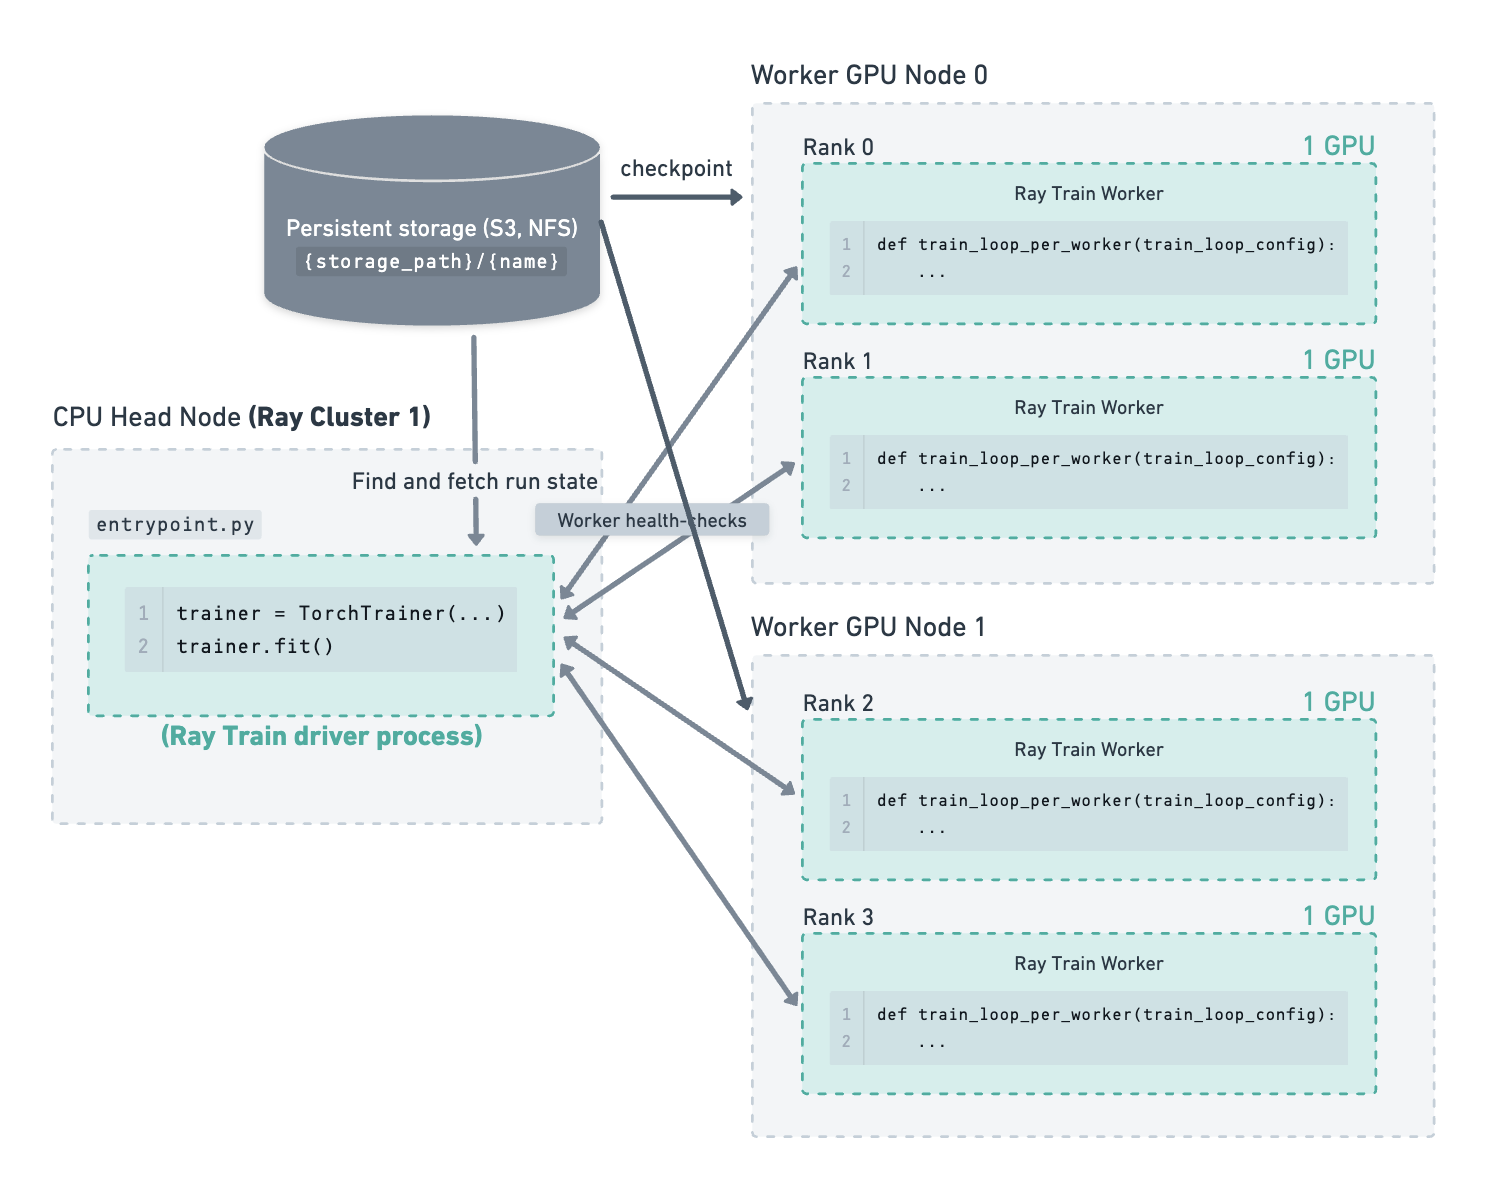
A manual cluster restart or a job submission system brings up a new Ray cluster.
The Ray Train driver process runs on a new head node.
Ray Train fetches the run state information from storage at {storage_path}/{name}, such as s3://my_bucket/my_run_name,
and passes the latest checkpoint to the newly launched worker processes to resume training.#
Fault tolerance API deprecations#
<Framework>Trainer.restore API deprecation#
The <Framework>Trainer.restore and <Framework>Trainer.can_restore APIs are deprecated as of Ray 2.43 and will be removed in a future release.
Motivation#
The old API saved user code to pickled files, which could cause deserialization issues that left runs unrecoverable.
It also made configuration confusing. The old API loaded some configurations from the pickled files, required you to re-specify certain arguments, and accepted optional re-specification of another subset of arguments. As a result, it was unclear which configuration the restored run used.
Migration steps#
To migrate from the old <Framework>Trainer.restore API to the new pattern, do the following:
If you use Ray 2.50 or earlier, enable the environment variable
RAY_TRAIN_V2_ENABLED=1.Replace
<Framework>Trainer.restorewith the regular<Framework>Trainerconstructor, and pass the samestorage_pathandnameas the previous run.
<Framework>Trainer(restore_from_checkpoint) API deprecation#
The <Framework>Trainer(restore_from_checkpoint) API is deprecated as of Ray 2.43 and will be removed in a future release.
Motivation#
This API was a common source of confusion and provided little value. It only set the initial value of ray.train.get_checkpoint() and didn’t load any other run state.
Migration steps#
Pass the initial checkpoint through the train_loop_config argument instead. For a code example, see the Train V2 migration guide in the following section.
Additional resources#
Train V2 migration guide: Full migration guide for Train V2
Train V2 Ray Enhancement Proposal (REP): Technical details about the API change
Handling Failures and Node Preemption (Deprecated API): Documentation for the old API